
部署运维
基础设施

sandbase-harness
sandbaseai
Local-first, self-hosted AI agent runtime and MCP bridge with sandboxed sessions, memory, credentials, audit/replay, and a local Console.
PROJECT TOPICS
PROJECT README
Part of the dsh-toolkit family: dsh-mcp-bridge · dsh-win-toolkit · dsh-netassist · dsh-driftwatch
Behavior-drift reports for DeepSeek Harness agents.
You changed a prompt, a plugin, or a model. Something feels different. But what changed — and by how much?
DriftWatch reads two session logs and tells you exactly how the agent's behavior diverged: tool-call sequence, tool mix, file targets, reasoning volume, retries, timing. Zero dependencies. CI-ready.
中文文档见 README.zh.md。
DSH logs everything (Model-visible means logged), so the evidence already exists — but reading a 59 MB trajectory by hand is not a workflow. Existing tools solve adjacent problems:
| Tool | Answers |
|---|---|
dsh-replay |
"show me this trajectory" (debugging) |
dsh-eval-harness |
"does this match my written expectations?" (assertions) |
dsh-driftwatch |
"how does this run differ from that run?" (comparison) |
DriftWatch deliberately does not assert and does not render trajectories. It produces a drift report: a structured, reviewable statement of behavioral change, plus an optional threshold gate for CI.
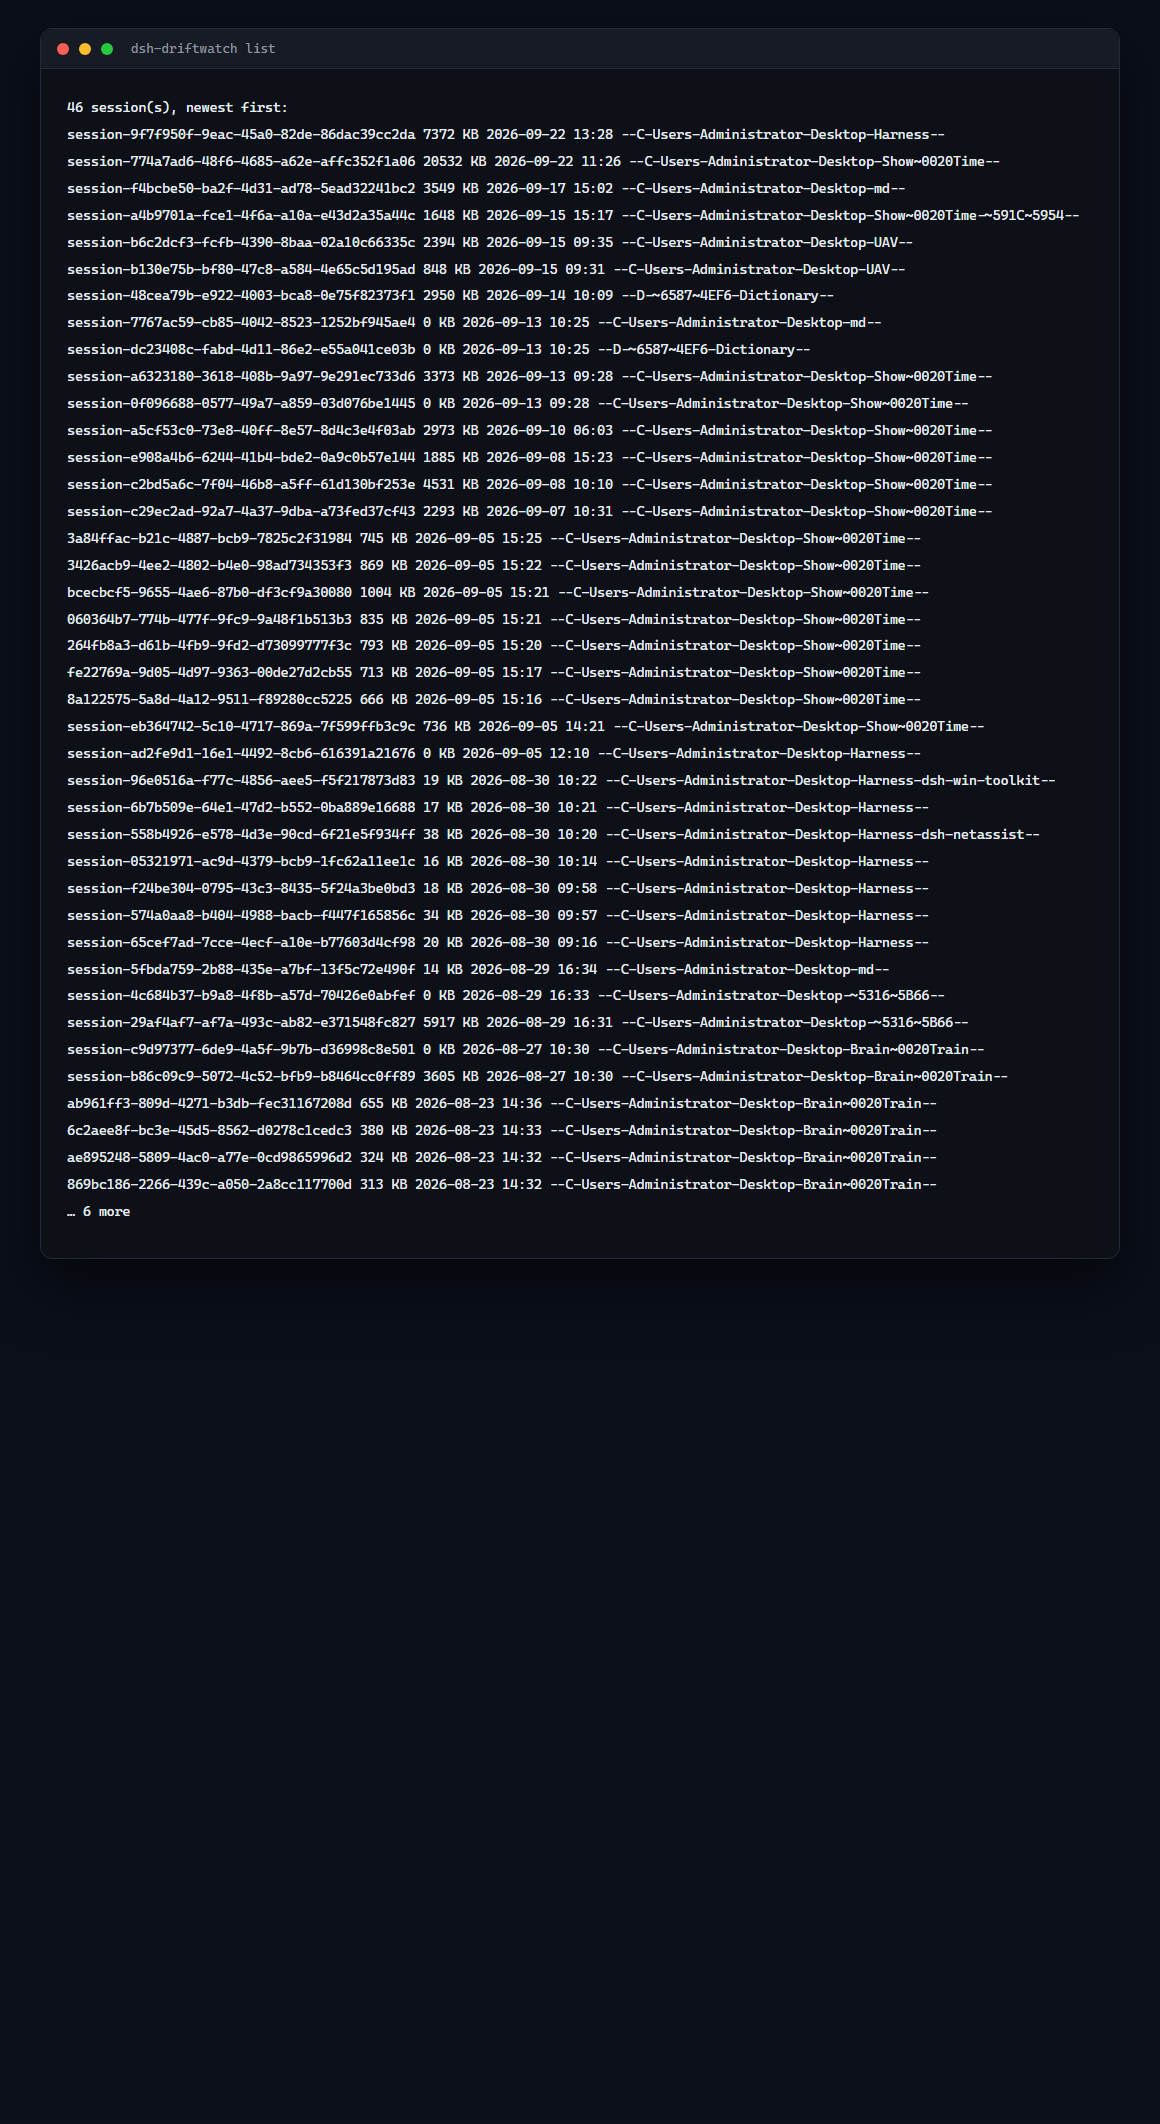
# list sessions under $DSH_HOME/sessions
npx dsh-driftwatch list

# compare two runs (id, id prefix, or path)
npx dsh-driftwatch compare session-b6c2dcf3 session-b130e75b

# CI gate: fail when drift reaches 35/100
npx dsh-driftwatch compare before after --fail-on-drift 35 --markdown drift.md
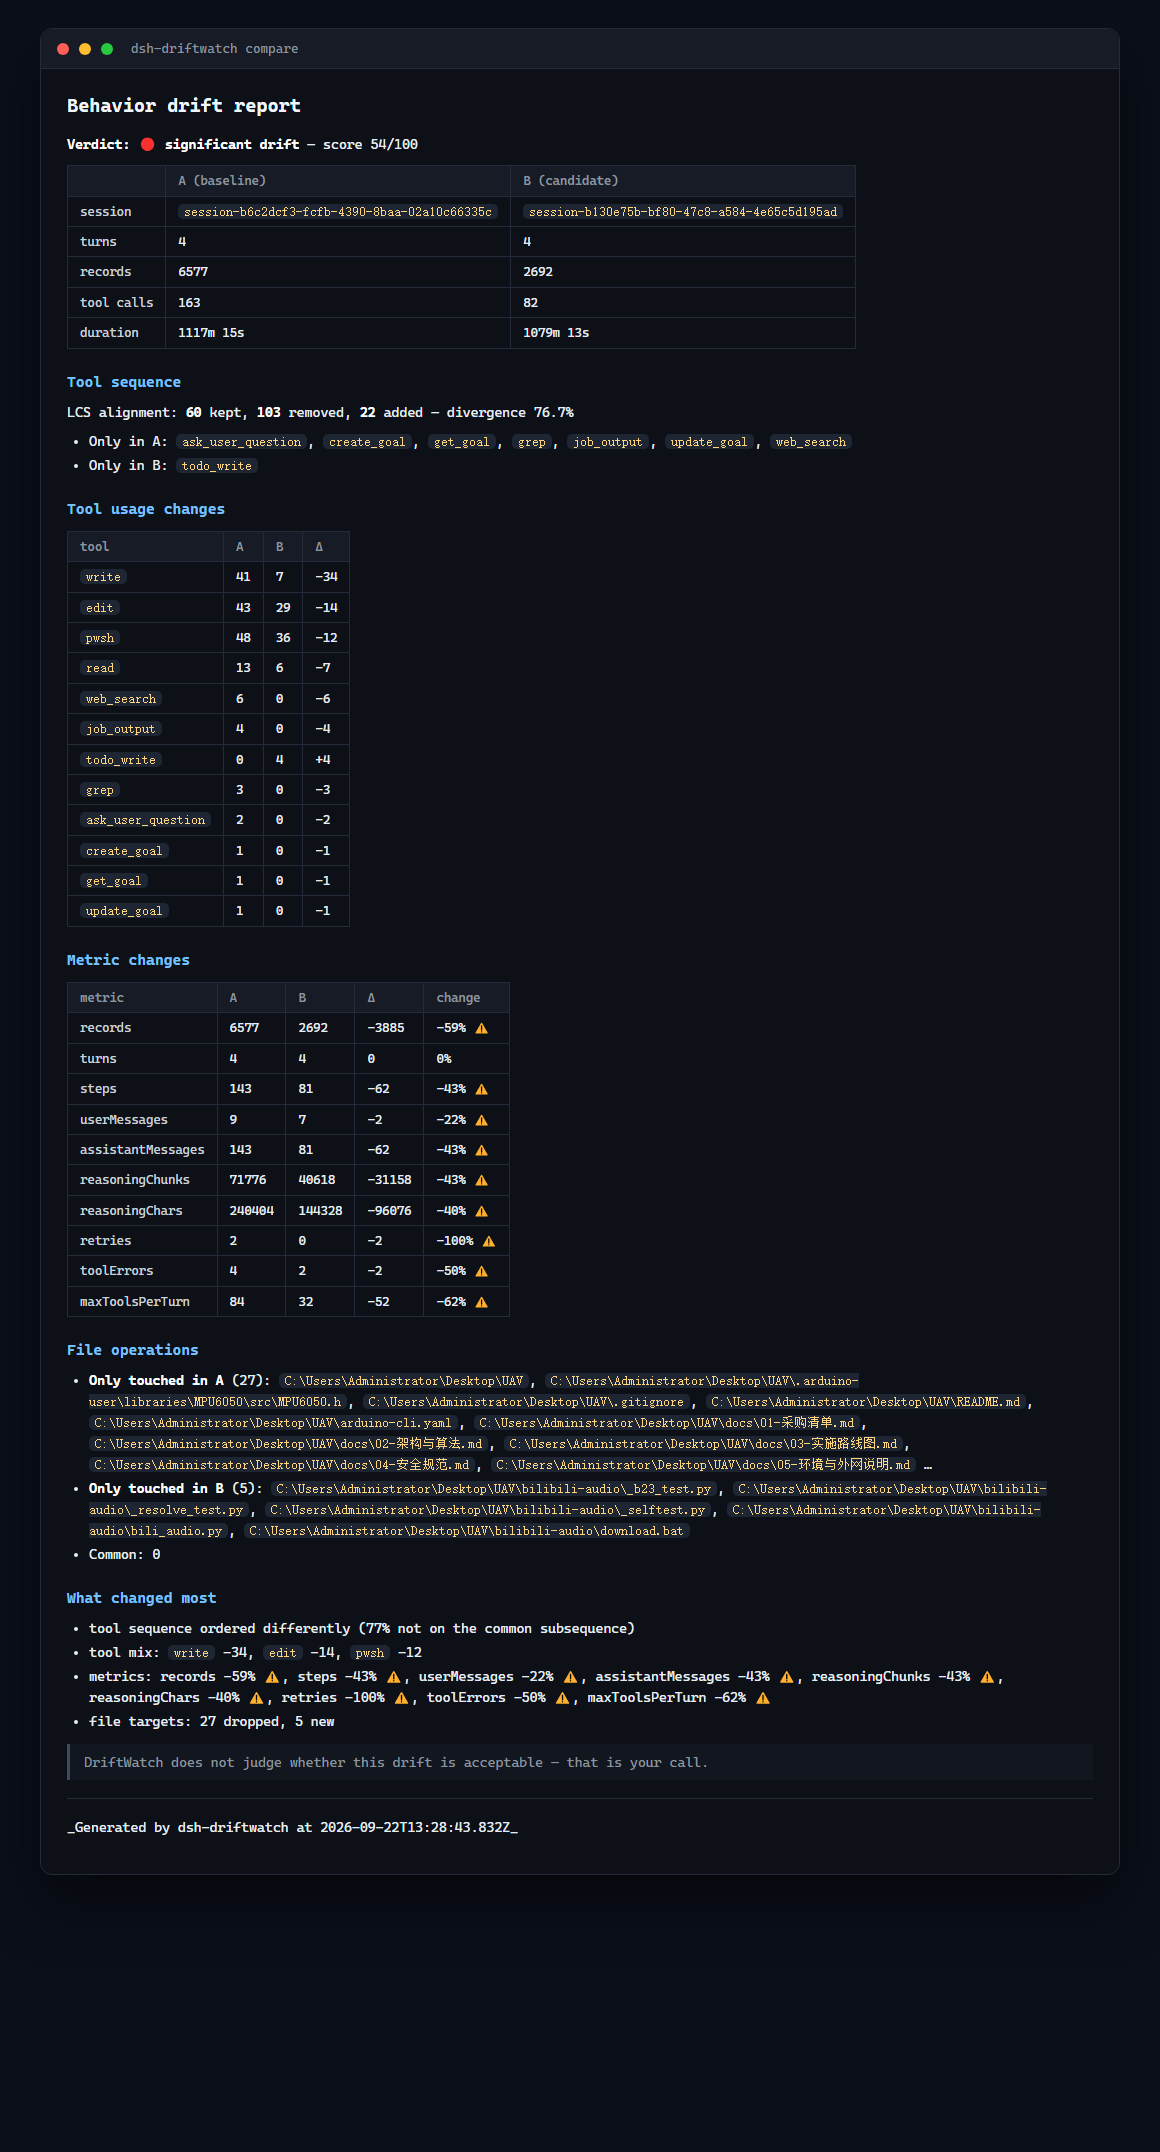
Real output from two actual runs:
**Verdict: 🔴 significant drift** — score 54/100

| | A (baseline) | B (candidate) |
|---|---|---|
| turns | 4 | 4 |
| records | 6577 | 2692 |
| tool calls | 163 | 82 |
| duration | 1117m 15s | 1079m 13s |

## Tool usage changes
| tool | A | B | Δ |
|---|---:|---:|---:|
| `write` | 41 | 7 | -34 |
| `edit` | 43 | 29 | -14 |
| `pwsh` | 48 | 36 | -12 |
| `todo_write` | 0 | 4 | +4 || Signal | Detail | Weight |
|---|---|---|
| Tool sequence | LCS alignment: kept / removed / added, divergence % | 40% |
| Tool mix | per-tool count deltas across both runs | 25% |
| Metrics | records, turns, steps, messages, reasoning chunks/chars, compactions, retries, tool errors, max tools per turn | 20% |
| File targets | paths touched in only A / only B / both | 15% |
Those weights combine into a 0–100 drift score with three tiers: stable (<10), moderate (10–34), significant (≥35).
DriftWatch never decides whether drift is acceptable — that judgment stays with you. The score and thresholds are just a way to make the change visible.
# .github/workflows/drift.yml
- name: Behavior drift check
  run: |
    npx dsh-driftwatch compare "$BASELINE_SESSION" "$CANDIDATE_SESSION" \
      --fail-on-drift 35 --markdown drift-report.md
- uses: actions/upload-artifact@v4
  if: always()
  with:
    name: drift-report
    path: drift-report.md
--json emits the full machine-readable report (scores, deltas, file sets) for dashboards or PR bots.
Installing it into a profile also gives the agent two tools:
dsh plugin --profile web add dsh-driftwatch| Tool | What the agent can do |
|---|---|
drift_compare |
compare two sessions and report the drift inline |
drift_list |
list available sessions to pick a baseline |
Useful for "compare how you did this task this time vs last time" — the agent gathers its own evidence.
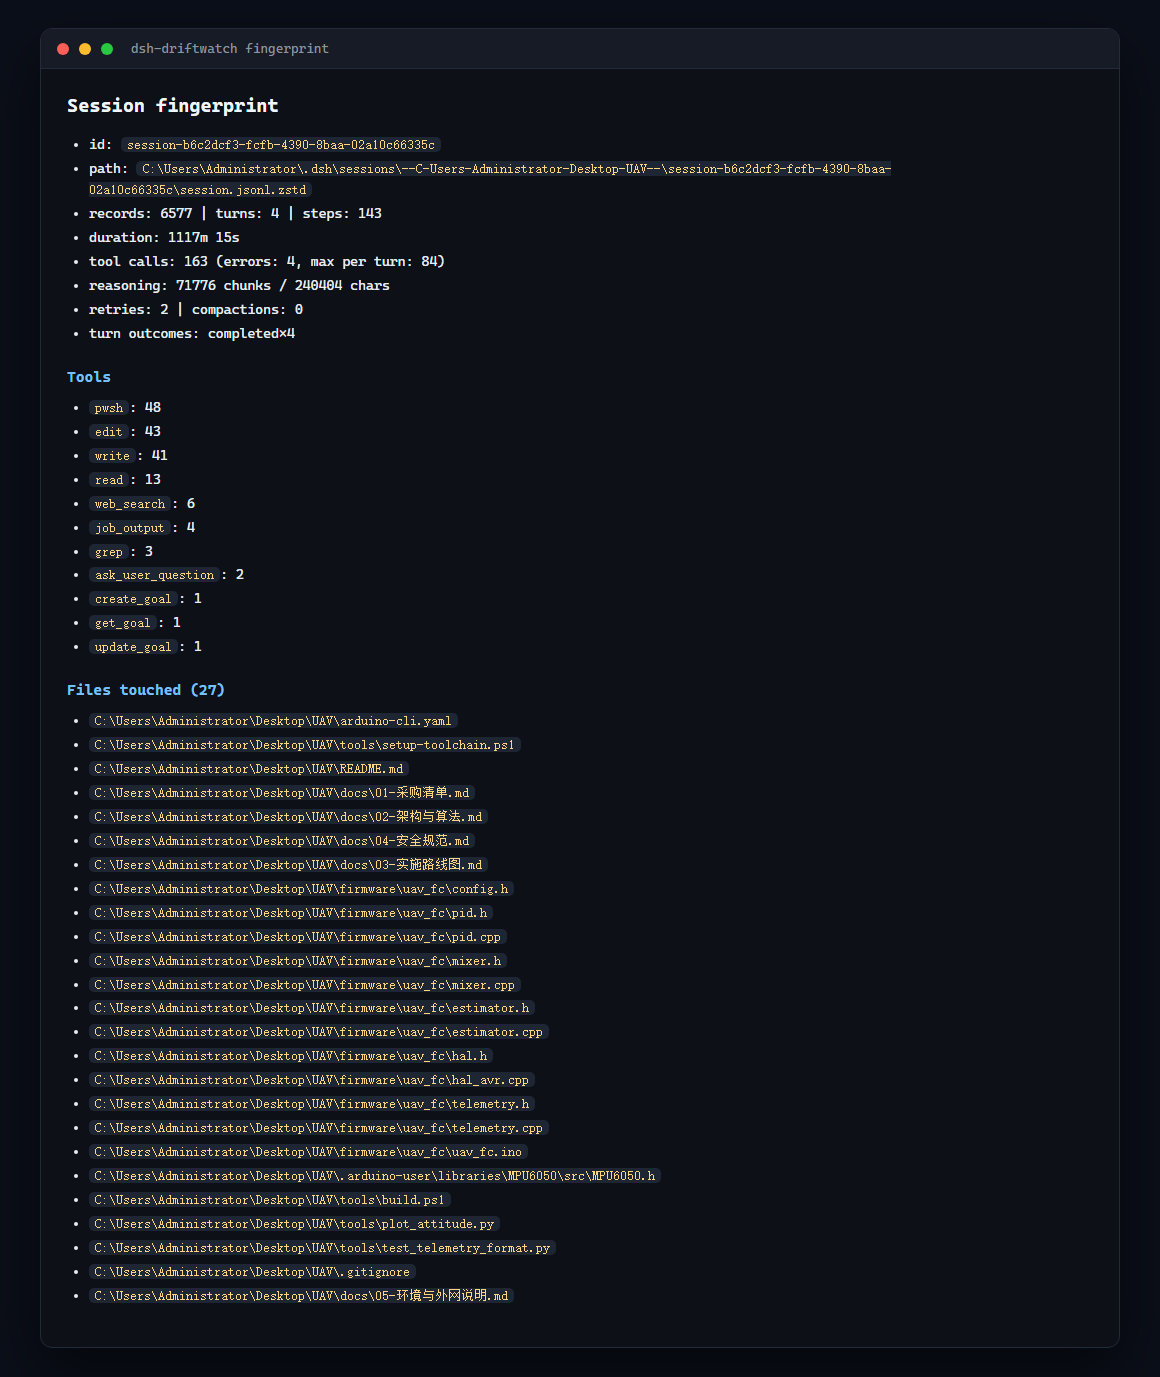
DSH session logs are append-only .jsonl.zstd: every append is a separate zstd frame, so a log is a concatenation of frames. Node's zlib decodes only the first frame and its stream API rejects the rest; DSH itself relies on a private zstd handle plus a koffi FFI fallback.
DriftWatch stays dependency-free with a self-healing strategy: scan for the zstd frame magic (28 B5 2F FD), then greedily decode from each candidate start until a slice decodes cleanly. Measured on a 20 MB / 34 729-frame log: full 59 MB decode in ~1.4 s.
MIT
CLASSIFICATION EVIDENCE
系统优先读取 GitHub Topics,再与站内分类词典和词根规则比对。当前命中: observability、regression-testing、session-log。
sandbaseai
Local-first, self-hosted AI agent runtime and MCP bridge with sandboxed sessions, memory, credentials, audit/replay, and a local Console.

Han-1413141
Cost tracking for DeepSeek Harness: session and model costs, token usage, budgets, provider balances, and coding-plan quotas. Bilingual English/Chinese UI.

weijiafu14
Bridge the Pi and DeepSeek Harness ecosystems: one Pi Host ABI runs unmodified Pi extensions as native DSH plugins. 打通 Pi 与 DSH 生态。