

其他
完整应用

deepseek-harness
deepseek-ai
DeepSeek Harness: Everything is a Plugin.
PROJECT TOPICS
INSTALL REFERENCE
dsh plugin --profile web add github:shimingming520/dsh-audiogen
该命令指向仓库当前默认分支;尚无绑定当前 commit 的完整验证结果。
PROJECT README
AI audio generation for DeepSeek Harness (DSH) — turn your DSH web GUI into an audio studio: text-to-speech, music, sound effects and voice design, from the sidebar panel or straight from the Agent.


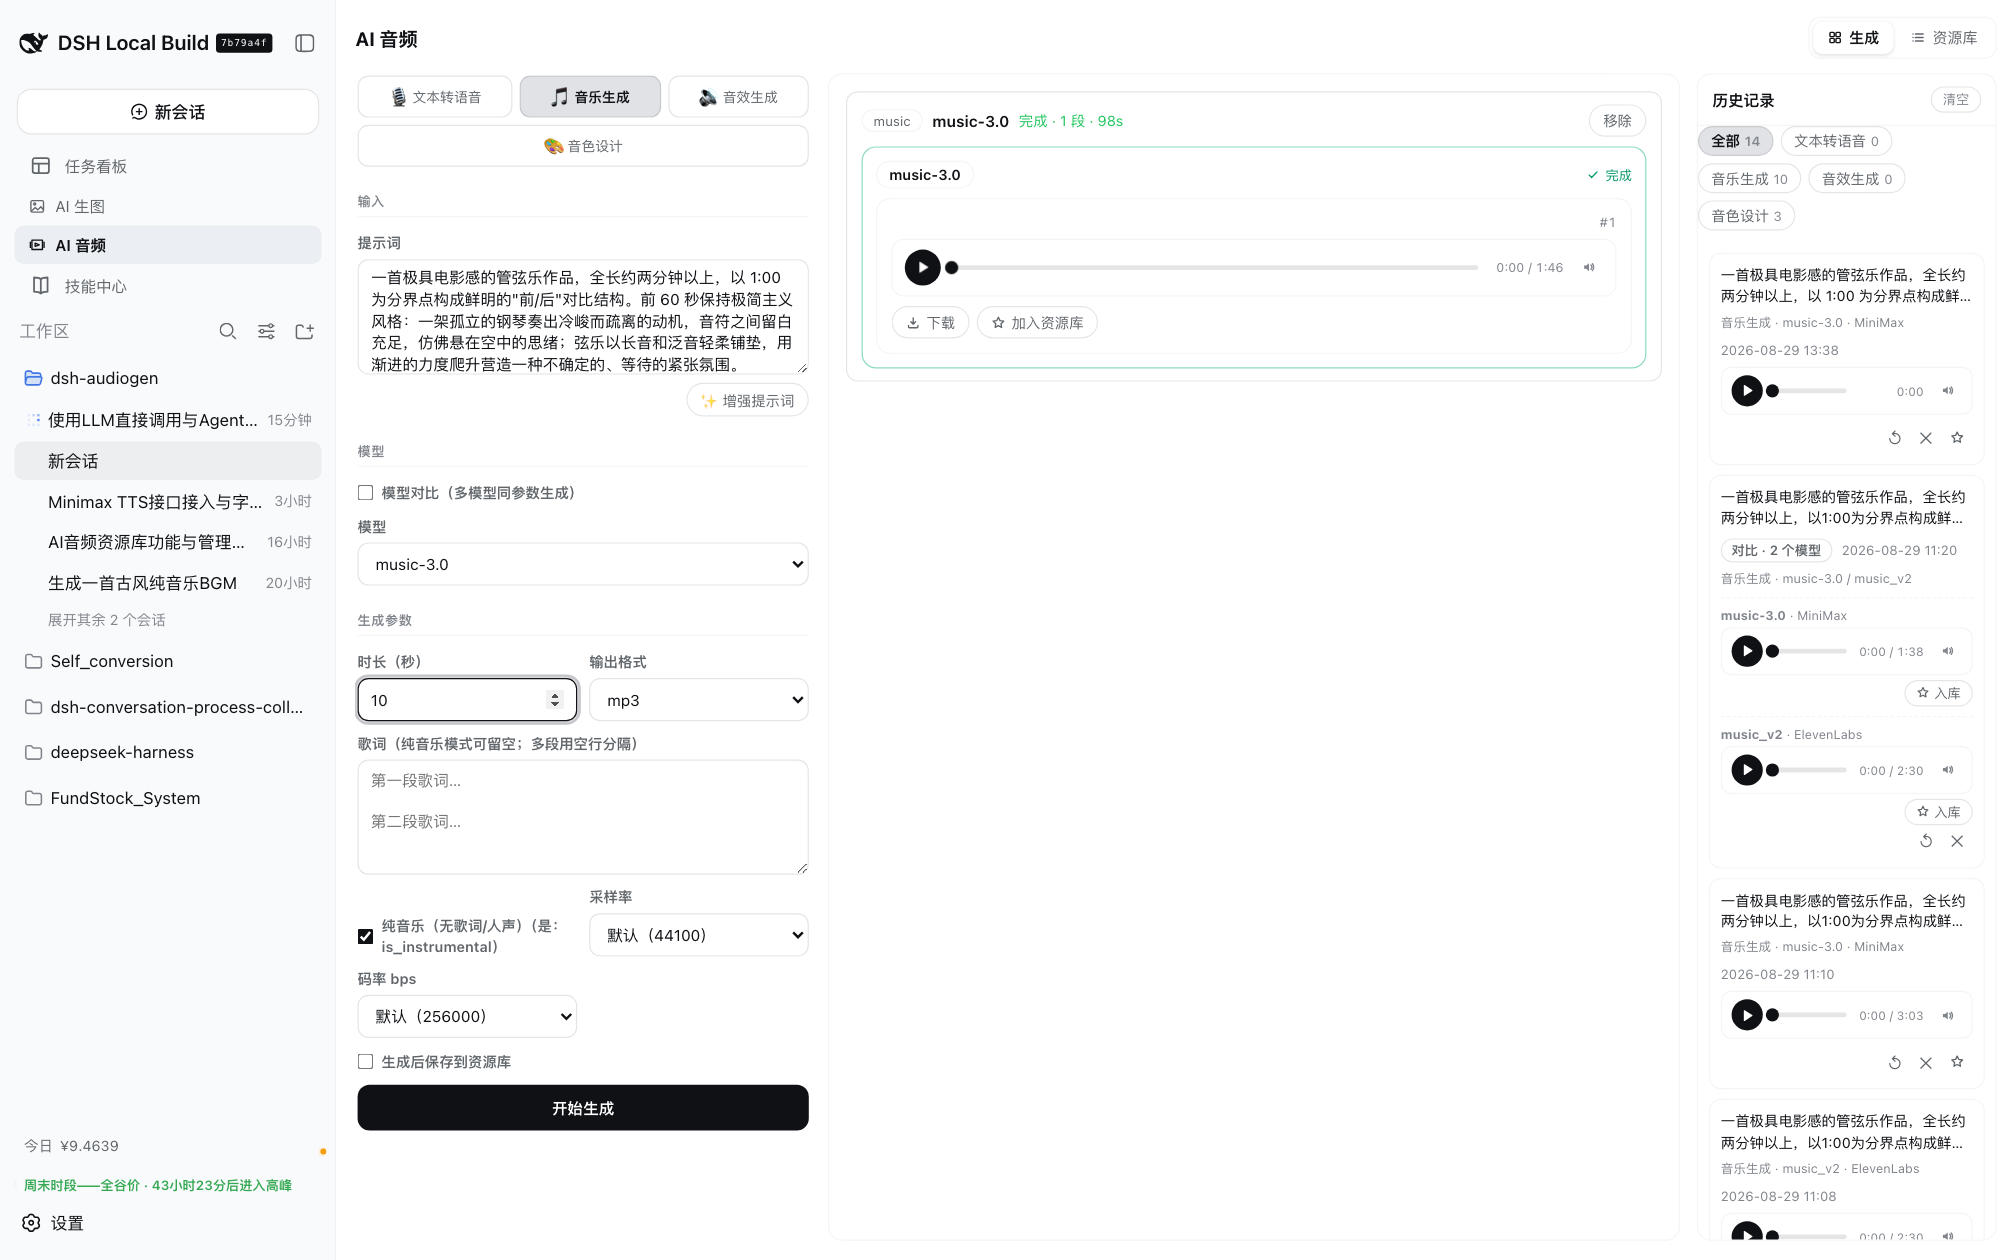
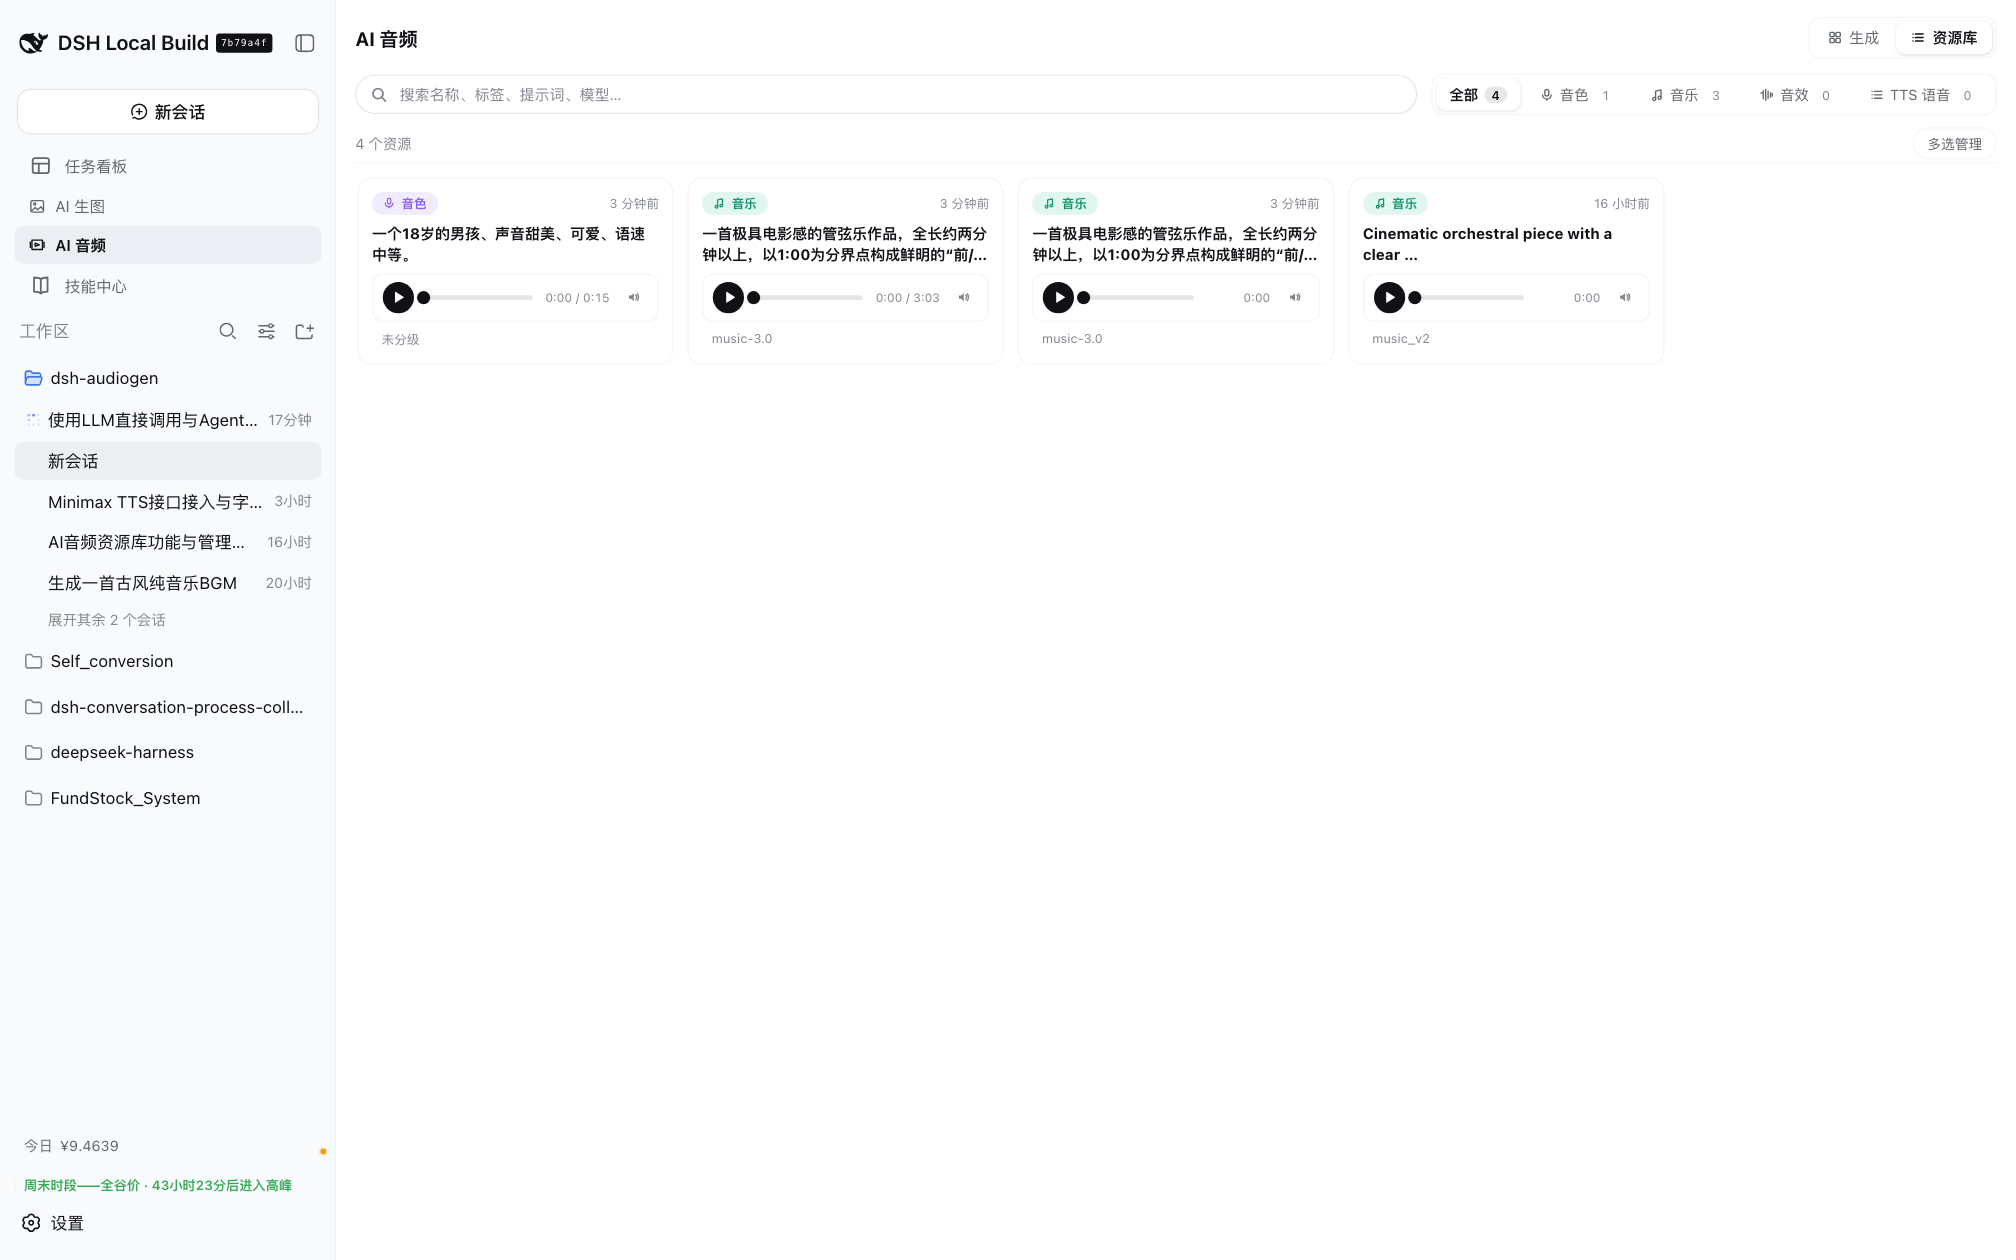
output_format, …)generate_audio and search_audio_library, manage_audio_voices (vendor voice browsing/deletion + prompt-based voice recommendation + role voice casting), plus bundled session skills — the Agent can generate and find audio on demandmanage_audio_voices action=cast takes character profiles (JSON array/object or a text description structured first) and applies deterministic hard filters (gender/age/use_case strict; accent is a preference relaxed only when the strict pool is empty) per character; the Agent picks voices globally (no primary reuse across lead/major roles) and action=save_cast validates membership, auto-fills backups, flags reuse and persists the plan to ~/.dsh/dsh-audiogen/cast-selections.json; then TTS with the chosen voice_id (or design a custom voice first via generate_audio(mode=voice_design))voice_id into the TTS form; every AI recommendation is recorded automatically (last 50, shared by panel and Agent) so you can revisit requirements/channels/reasons and reuse a voice later| Generation panel | Resource library |
|---|---|
|
 |
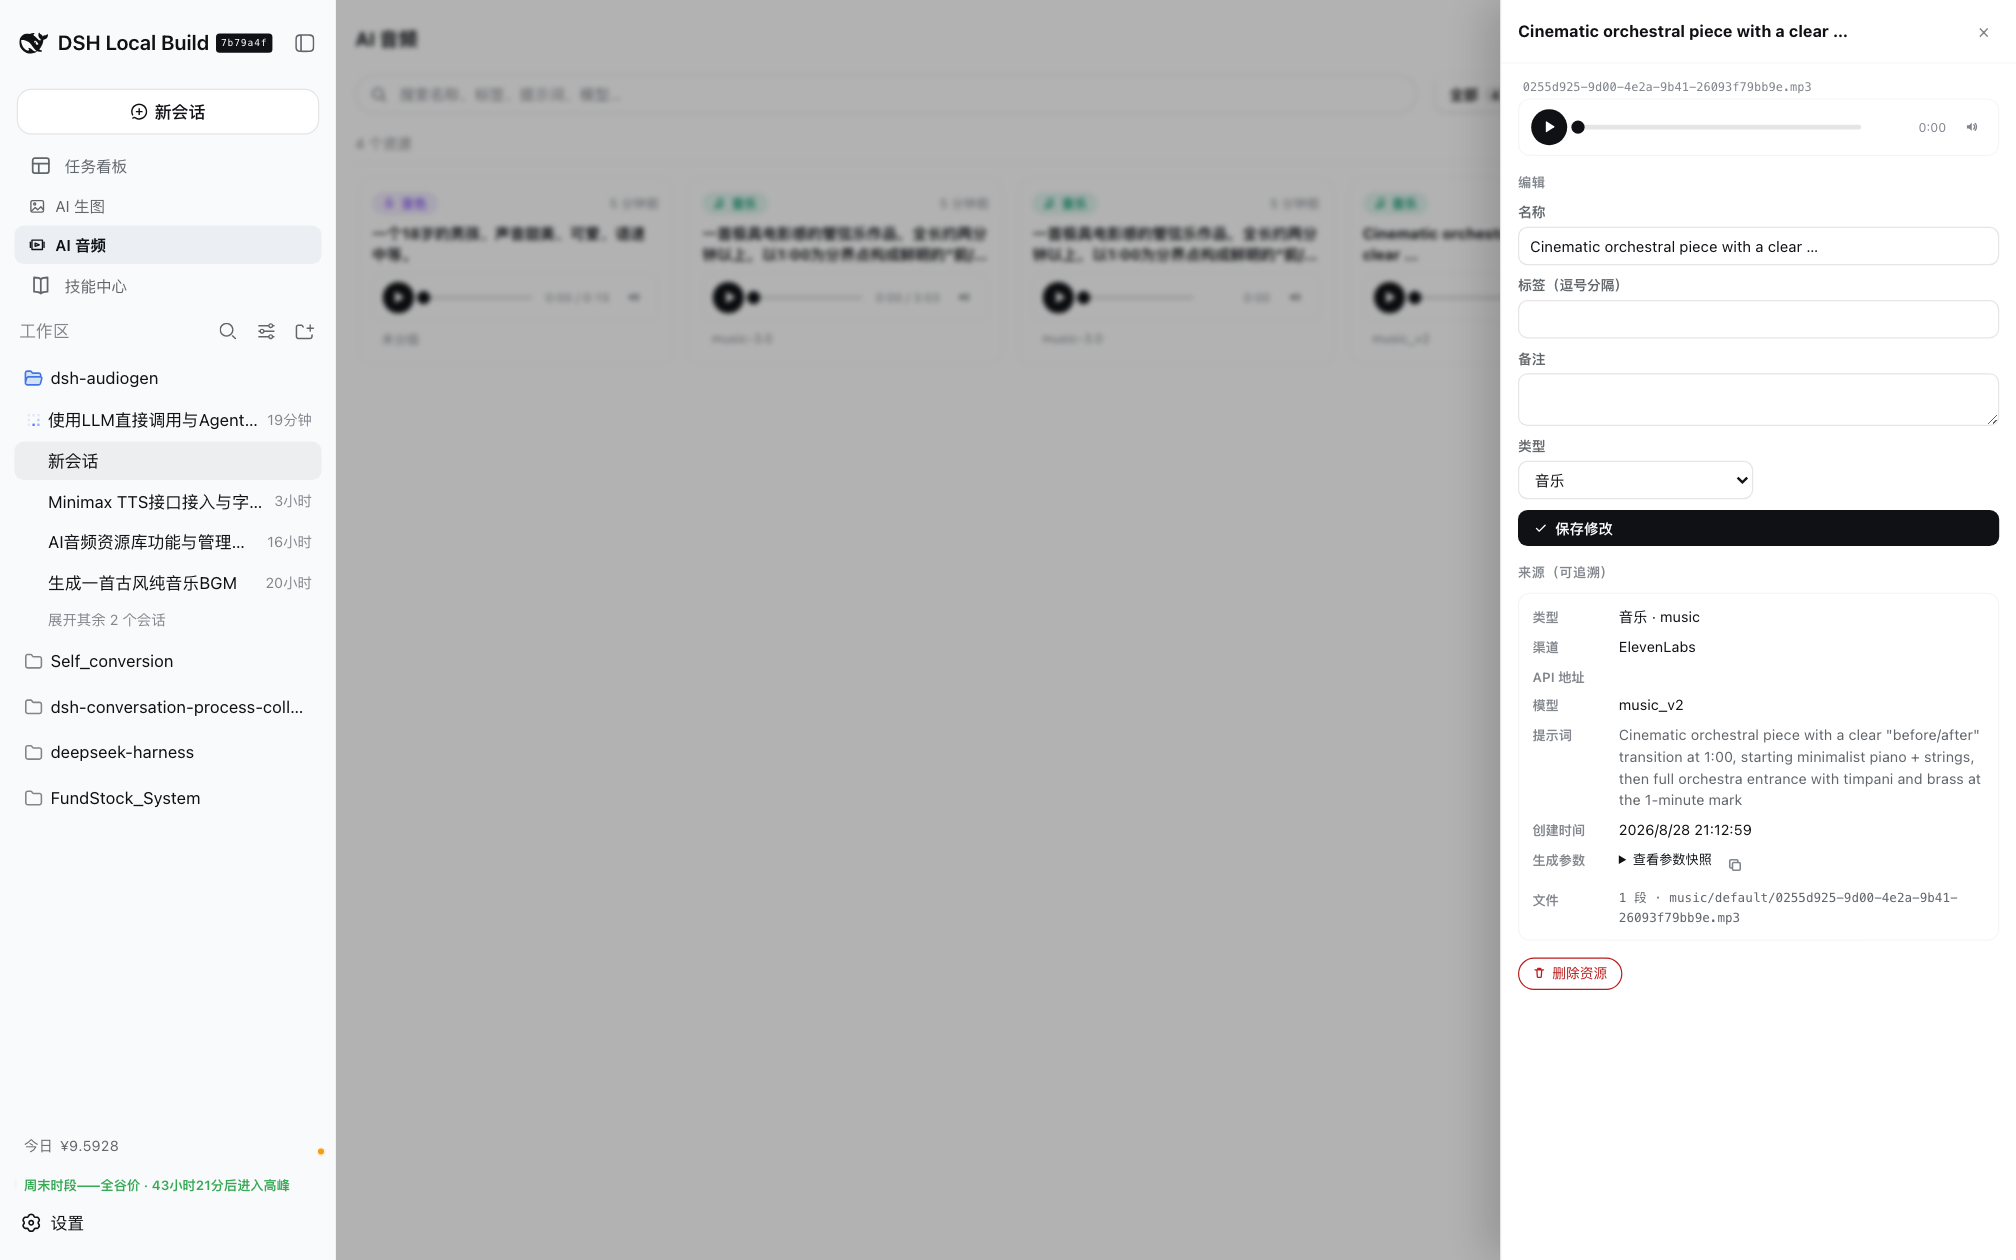
| Library — full provenance drawer | Channels settings |
|---|---|
 |
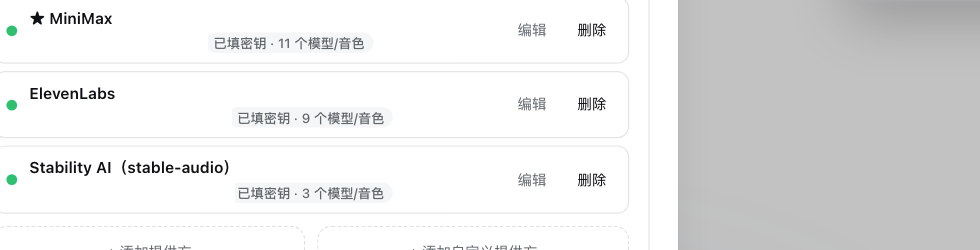 |
| Channel editor (model catalog & auto capabilities) | LLM models (Settings → Models) |
|---|---|
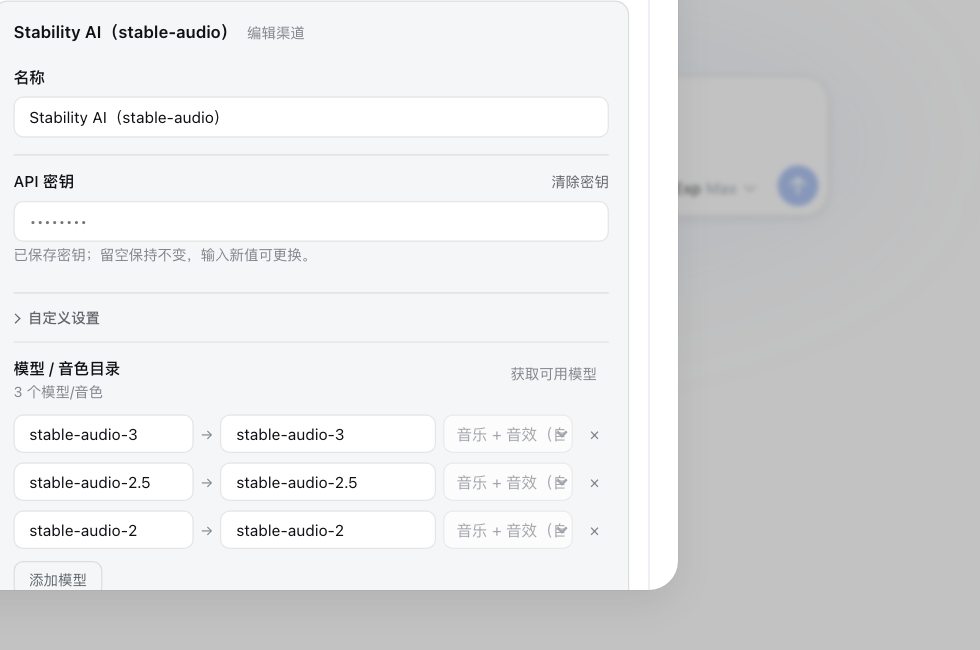 |
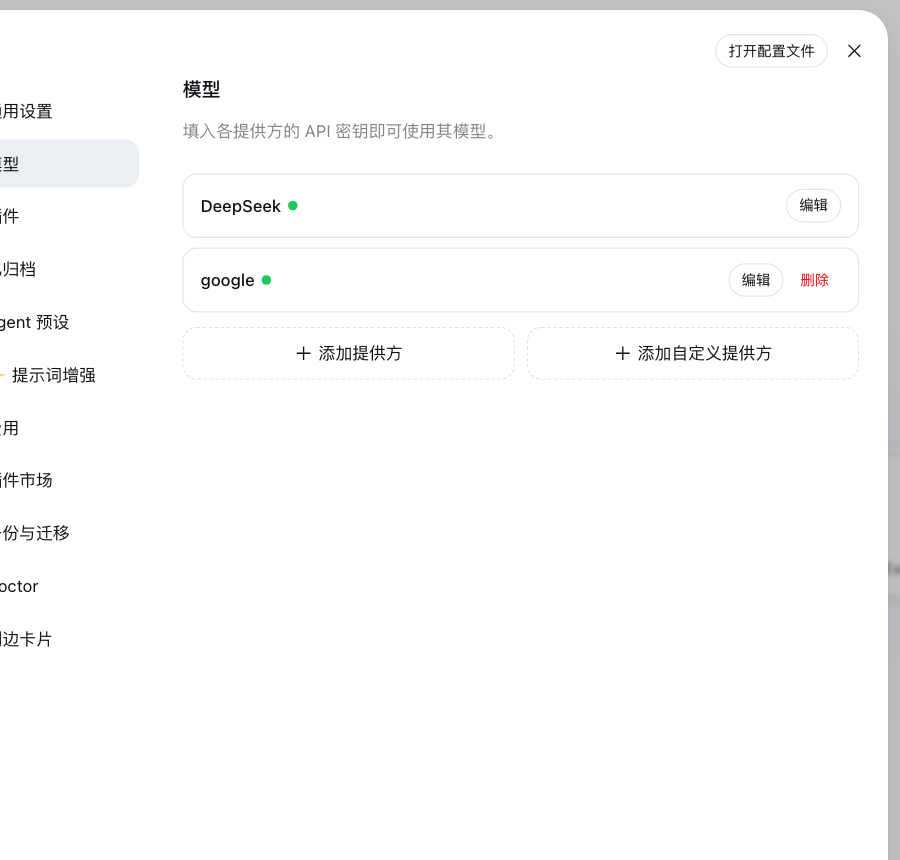 |
The plugin is published on npm. DSH host (Node ≥ 20) required.
dsh plugin --profile web add dsh-audiogenLocal development install:
dsh plugin --profile web add /path/to/dsh-audiogenRestart dsh web after install — the sidebar will show the AI Audio entry.
| Mode | MiniMax | ElevenLabs | Stability AI | OpenAI-compatible / custom |
|---|---|---|---|---|
| TTS | ✅ (8 voices) | ✅ (voices + streams) | — | ✅ |
| Music | ✅ (music-3.0 / music-2.6 / music-cover) |
✅ (music_v2) |
✅ (stable-audio-*) |
✅ (generic POST) |
| Sound effects | — | ✅ (eleven_text_to_sound_v2, loop / prompt influence / output format as codec+sample rate+bitrate → output_format) |
✅ (stable-audio-* — same text-to-audio protocol; auto-detected in both Music and SFX) |
✅ (generic POST) |
| Voice design | ✅ (/v1/voice_design) |
✅ (/v1/text-to-voice/design) |
— | — |
| Tool | Purpose |
|---|---|
generate_audio |
Submit a TTS / music / SFX / voice-design task; waits for completion and returns same-origin audio URLs. Optional enhance_prompt, save_to_library, per-vendor params. |
manage_audio_voices |
Browse/filter the vendor voice libraries (MiniMax, ElevenLabs) with language/keyword/source filters; recommend top-k voices for a natural-language requirement (action=recommend, uses the agent default model, ids validated against the pool); role casting (action=cast prepares per-character filtered candidate pools from character profiles; action=save_cast validates + persists the plan); delete account-owned voices (official/shared/system voices are read-only and refused). Then use the returned voice_id with generate_audio (mode=tts). |
search_audio_library |
Search the local resource library (type / category / keyword) and reuse an existing voice, music bed or effect. |
Typical session commands (skills bundled with the plugin):
/audio:tts      Read this sentence with a warm voice
/audio:music    Generate a 30-second lo-fi background track
/audio:sfx      Create a sci-fi UI cue
/audio:design Craft a warm retro synth voice/api/dsh-audiogen/*, loopback-only routes)~/.dsh/dsh-audiogen/pnpm install
pnpm run typecheck
pnpm run build # outputs lib/ (host + client bundles)CLASSIFICATION EVIDENCE
系统优先读取 GitHub Topics,再与站内分类词典和词根规则比对。当前命中: 无有效分类标签。
deepseek-ai
DeepSeek Harness: Everything is a Plugin.

anywhere-labs
为 DeepSeek Harness (DSH) 插件生态打造的现代化桌面端解决方案。万物皆「插件」,桌面本身也是「插件」。

awesome-dsh-plugin
A curated list of plugins for DeepSeek Harness (dsh) · DeepSeek Harness 插件精选列表