RiskProof
Provenance-aware execution security for DeepSeek Harness.
Track where tool inputs came from. Detect risky cross-tool data flows. Stop sensitive side effects before execution.
English · 简体中文
Start here
See protection beside your conversation
A persistent RiskProof security beacon sits beside the DSH conversation. Ordinary tool
calls update it automatically. Click to open a compact overview; activity never opens it for you.
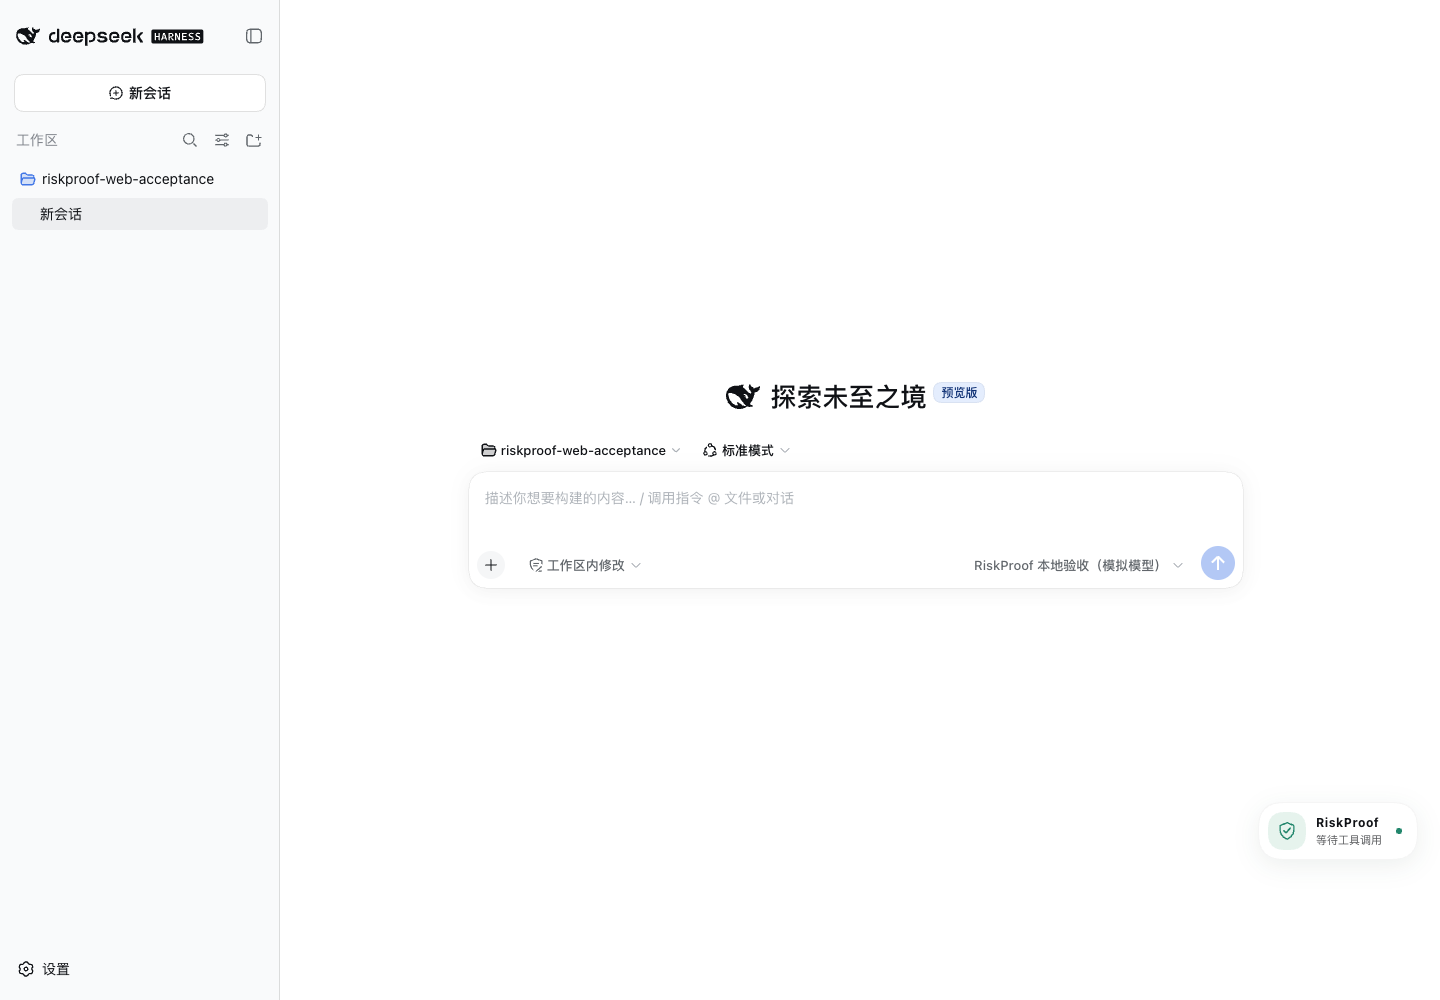
- Waits honestly for tool activity; there is no continuous simulated scan.
- Shows pending execution receipts and briefly acknowledges newly checked calls.
- Displays a call-distribution ring, the last 24 checks and up to three recent risk chains.
- Follows the selected conversation and removes stale charts when its connection is unavailable.
- Separates initial sync from disconnection, offers manual reconnect, and displays task scope and record limits.
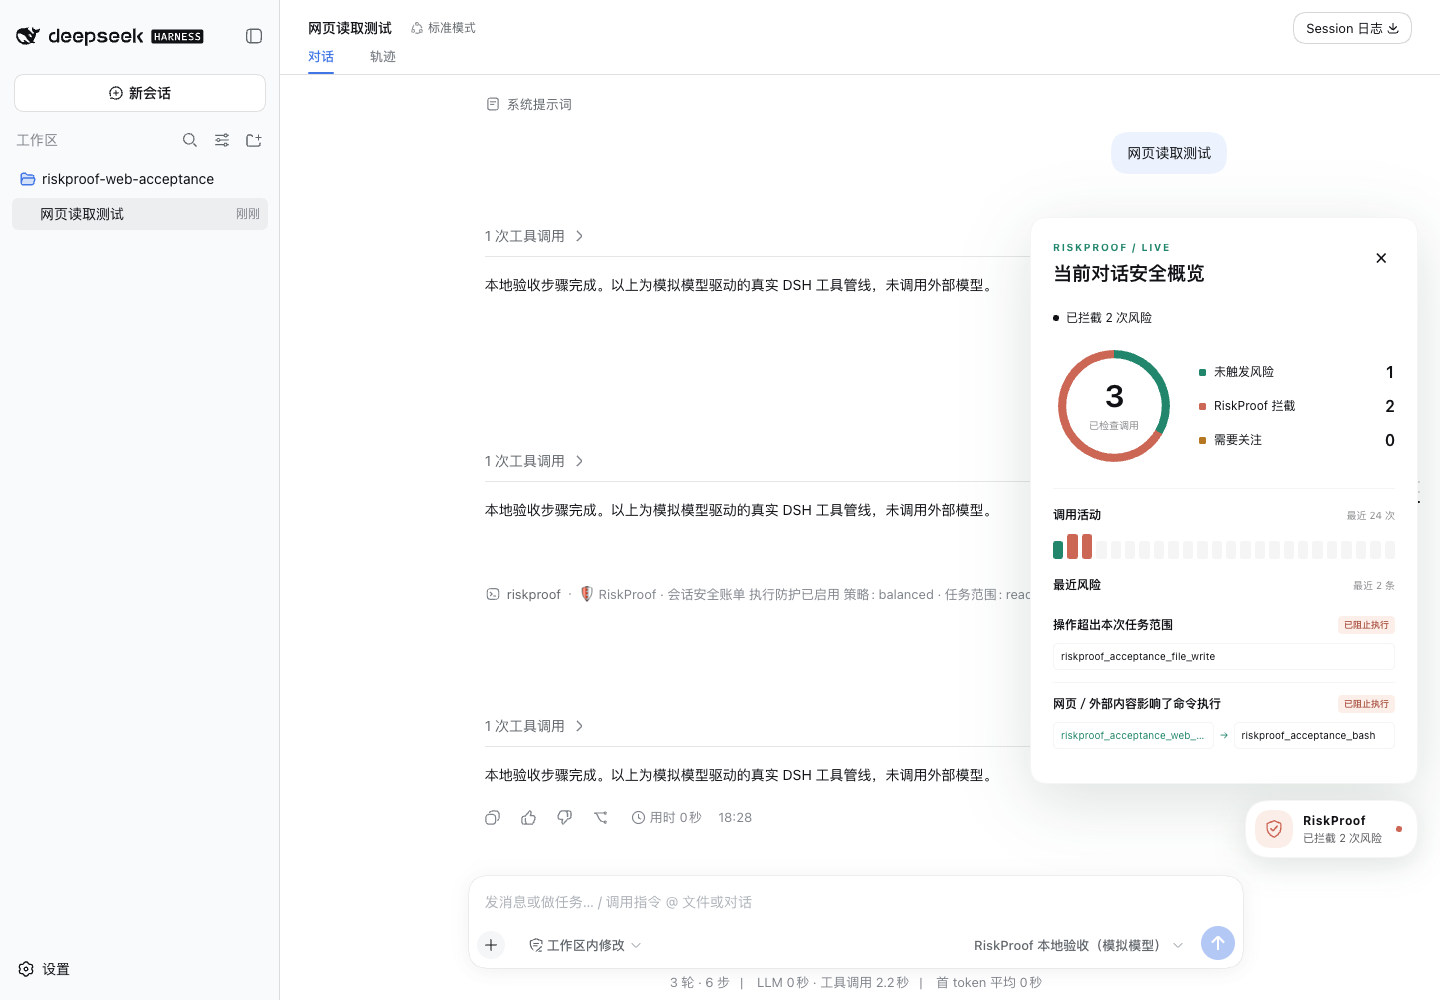
Real DSH Web screenshots; a local test model produced these records through the actual
Agent/tool pipeline. Normal use does not require a rehearsal.
The chart counts calls with no triggered risk, calls blocked by RiskProof, and calls needing
attention. It does not invent a safety score. Observe mode, disabled recording and disabled
detection features are identified. Counts cover retained records in the current plugin run.
Not triggering a rule does not establish that an operation is safe.
Commands remain secondary entries; long output is collapsed by default:
| Need |
DSH command |
| Open the compact overview |
/riskproof |
| Read the text provenance report |
/riskproof trace |
| Restrict to inspection |
/riskproof task read-only |
| Keep tool capabilities local |
/riskproof task local-only |
| Restore ordinary task scope |
/riskproof task standard |
| Optional isolated rehearsals |
/riskproof demo |
The model can also call the read-only riskproof_report tool. The beacon reads redacted
statistics through DSH's authenticated connection about once per second while the page is
visible. It makes no model requests and creates no tool records. The current beacon uses
Chinese labels; command/tool text supports Chinese and English (experience.language: en).
What RiskProof answers
Most tool-permission plugins answer one question: is this tool allowed?
RiskProof answers a different one:
Where did the data in this tool call come from, what did it flow through, and where is it about to go?
A single tool call is usually safe. The composition is not.
web_fetch          ← UNTRUSTED_WEB
   │
database_query     ← CUSTOMER_DATA
   │
send_email         ← external destination
   │
RiskProof → DENY   (evidence-backed, before the side effect)
Why RiskProof
| Permission rules |
RiskProof |
| Is this tool allowed? |
Where did this data come from? |
| Single call |
Cross-tool flow |
| Tool name |
Provenance + taint |
| Static rule |
Stateful attack chain |
| Permission decision |
Evidence-backed execution decision |
RiskProof is a layer over the DSH Tool Runtime, not another Agent Runtime. It never re-implements tool dispatch, approval, or lifecycle — it observes and decides.
Quick Start
Requires Node.js 22.19+, with DSH and pnpm installed. Install or update:
dsh plugin --profile web add dsh-riskproof@0.4.1
Alternatively, build a local package from the repository root:
# build and install from this checkout
npm ci
mkdir -p artifacts
npm pack --pack-destination artifacts
dsh plugin --profile web add ./artifacts/dsh-riskproof-0.4.1.tgz

# confirm the bundled patch was composed
dsh --profile web --dump-config
The package declares a DSH bundle, so plugin add composes its riskproof row automatically. No second install or manual row is required. Restart the profile to see the beacon, then click it to inspect the current conversation.
The current version is 0.4.1. See installation and update instructions. Installation, SDK host startup,
commands and tool execution have been verified on DSH 0.1.0-rc.7 and 0.1.2-rc.1.
Chrome desktop and narrow-viewport Web acceptance also passed on DSH 0.1.2-rc.1,
including provenance and read-only denials through the real Agent loop with a local
simulated model. See validation evidence.
To tune it, override the bundled row from the profile's later cordis.patch.yml layer:
- id: riskproof
  config:
    mode: enforce            # enforce | observe
    policy:
      preset: balanced         # permissive | balanced | strict
      internalDomains: [acme.internal]
      blockedDomains: [collector.evil.example]
      # allowedExternalDomains: [api.approved.example]
    classification:
      overrides:
        gmail_send: [EXTERNAL_ACTION]
        company_db: [PRIVATE_ACCESS]
    output:
      blockedTaints: [SECRET, API_KEY]
      # trustedDeclassifiers: { approved_redactor: [PII] }
See docs/configuration.md for the full reference.
See it work
sequenceDiagram
    participant A as Agent
    participant T as DSH ToolRuntime
    participant R as RiskProof

    A->>T: web_fetch(url)
    T->>R: tools/pre-execute
    R-->>T: allow (EXTERNAL_INGESTION recorded)
    T-->>A: untrusted content

    A->>T: database_query(sql)
    T->>R: tools/pre-execute
    R-->>T: ask (operator approves private access)
    T-->>A: CUST-8842 balance 125000

    A->>T: send_email(to=external, body=CUST-8842…)
    T->>R: tools/pre-execute
    R-->>T: DENY — ingestion + private access + sensitive data + external action
    T-->>A: Error: <reason>
The same flow is reproduced as a deterministic regression test in tests/security/attack-chain.test.ts.
Try it locally with no model or profile — a real DSH ToolRuntime pipeline with three mock tools:
npm run demo
See demo/README.md.
Features
Track data origin
Know where tool inputs came from. RiskProof maps arguments back to the tool results that produced them.
Follow sensitive data
Carry security labels — UNTRUSTED_WEB, CUSTOMER_DATA, PII, SECRET, … — across tool calls, additively.
Control sensitive output
Inspect model-facing results in tools/post-execute; block SECRET and API_KEY output by default before it enters model context.
Declassify through pinned tools
Let exact operator-approved tools remove selected inherited labels. Labels detected in the returned value are always restored, so a redactor must actually remove the sensitive data.
Detect attack chains
Identify the EXTERNAL_INGESTION → PRIVATE_ACCESS → EXTERNAL_ACTION pattern that single-tool checks miss.
Stop before execution
Block or ask before the side effect runs, through the native tools/pre-execute gate.
Guard sensitive surfaces
Gate credential-file paths, high-confidence destructive commands, download-and-execute pipelines, blocked destinations, and credentials embedded in network-capable commands.
Adapt without rewriting rules
Start with the default balanced preset, roll out with permissive, or use strict; every configurable decision can still be overridden individually.
Explain every decision
Generate structured, privacy-preserving security evidence and actionable remediation for every decision. Keep proofs in memory or append them to an operator-controlled JSONL file.
How it works
RiskProof hooks the native DSH tool pipeline:
tools/pre-execute
    │  capability classification
    │  argument provenance mapping
    │  taint analysis
    │  toolchain state (EIT → PAT → NAT)
    │  deterministic policy evaluation
    ▼
allow / ask / deny   (monotonic with other plugins)
    │
tool execute
    │
tools/post-execute
    │  output taint evaluation
    │  trusted declassification
    ▼
accept / block
    │
tools/result
    │  update ContextTracker
    │  update Toolchain state
    ▼  record execution evidence
- Classification is deterministic (tool name + description + schema), configurable, and never uses an LLM.
- Provenance uses exact and bounded substring matching over a per-session context index.
- Taint is additive; only an exact operator-approved declassifier can remove selected inherited labels.
- Decisions are deterministic, explainable, and testable.
See docs/architecture.md.
Security boundaries
RiskProof protects supported observable tool-call flows through DSH:
- DSH tool calls through the supported
tools/pre-execute / tools/post-execute / tools/result paths
- supported observable provenance (exact / bounded substring matching)
- configured sensitive flows and cross-tool attack patterns
RiskProof does not replace:
- OS sandbox / process isolation
- network firewall / SSRF protection
- endpoint security / malware scanning
- credential vaults
- full semantic DLP
See docs/security-model.md for the complete threat model and known limitations.
Documentation
See the documentation index for guides, security design and version records.
Roadmap
v0.2 (delivered)
- DSH-native runtime (
tools/pre-execute, tools/result)
- Provenance + taint tracking
- Cross-tool EIT → PAT → NAT detection
- Privacy-preserving proof with optional JSONL persistence
- Policy presets, sensitive-path gates, deterministic command-risk checks, and egress domain policy
- Remediation guidance and per-rule proof statistics
v0.3 (delivered)
- Native security receipts, provenance timeline, bilingual reports and safe rehearsals
- Tool metadata continuity: description and input/output schema fingerprints
- Operator-selected task contracts: standard / read-only / local-only
- Execution-token correlation between policy gates and final results
- Taint inheritance through intermediate tools; bounded, isolated session state
v0.4 (current)
- Output-side information-flow control before results reach model context
- Default credential-output blocking with configurable label selection
- Exact-name trusted declassifiers with deterministic re-tainting
- Redacted output-control and declassification receipts
Later
- Richer structured/semantic DLP adapters
- Cross-process provenance with explicit trust boundaries
Contributing
Issues, rule submissions, tool-capability mappings, and false-positive reports are welcome. See CONTRIBUTING.md.
Security reporting
Please report vulnerabilities privately. See SECURITY.md.
License
Apache-2.0


