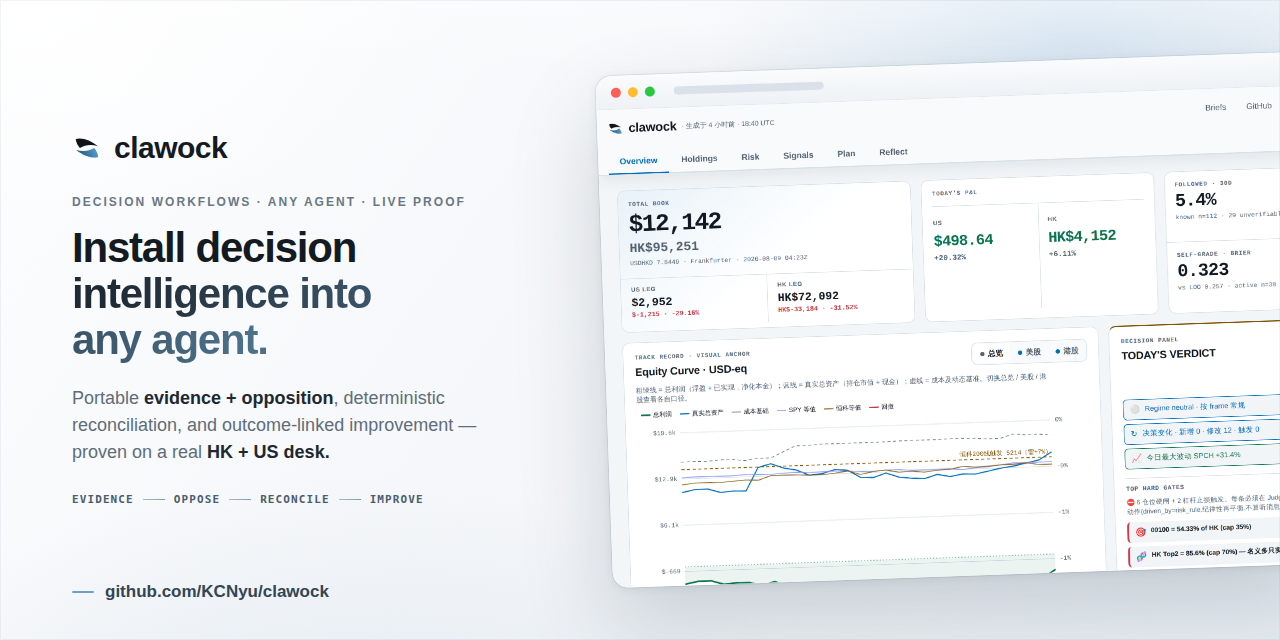
AI argues. Code settles. The losses stay on the page. A real HK + US brokerage account run by agents that must debate every call, settled by code the model never touches. Install the same decision workflow into your own agent: OpenClaw, Claude Code, Codex, or DeepSeek Harness.
“The market doesn't care how confident the model was.”
142
985
159
44
5
0
days live on a real HK + US account
decisions on the public ledger
episodes settled by code
data modules across 8 layers
agent harnesses, one contract
scores the model wrote for itself
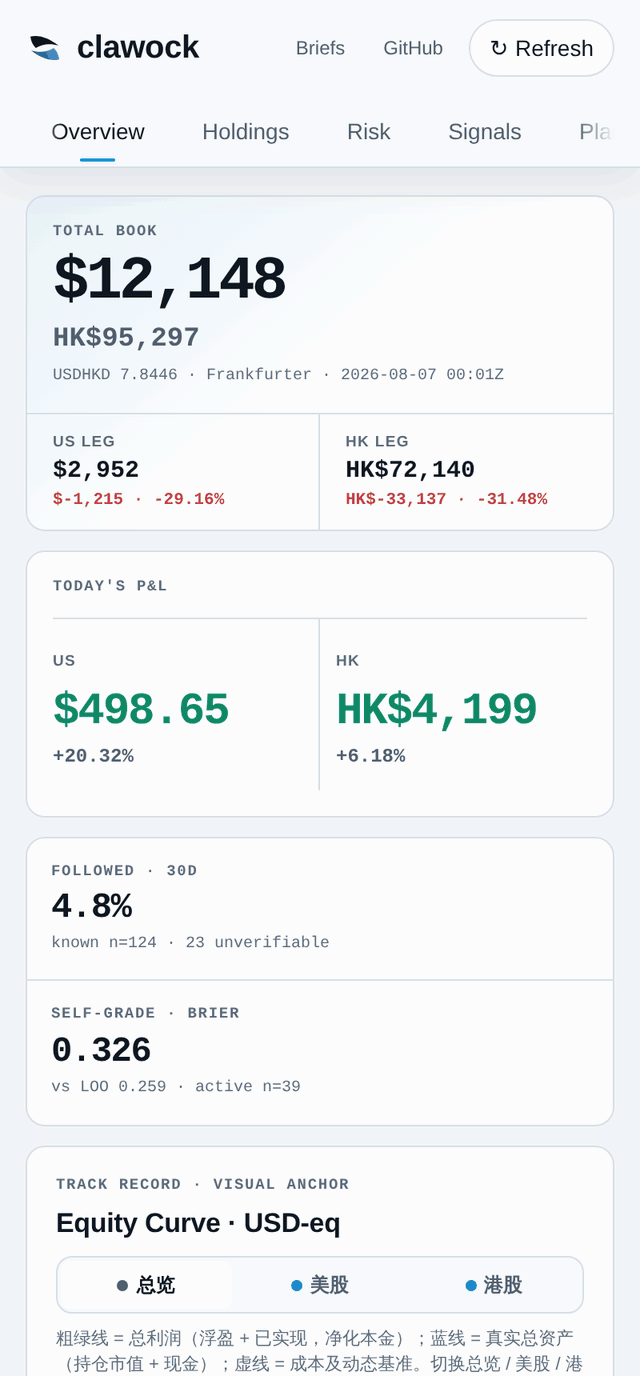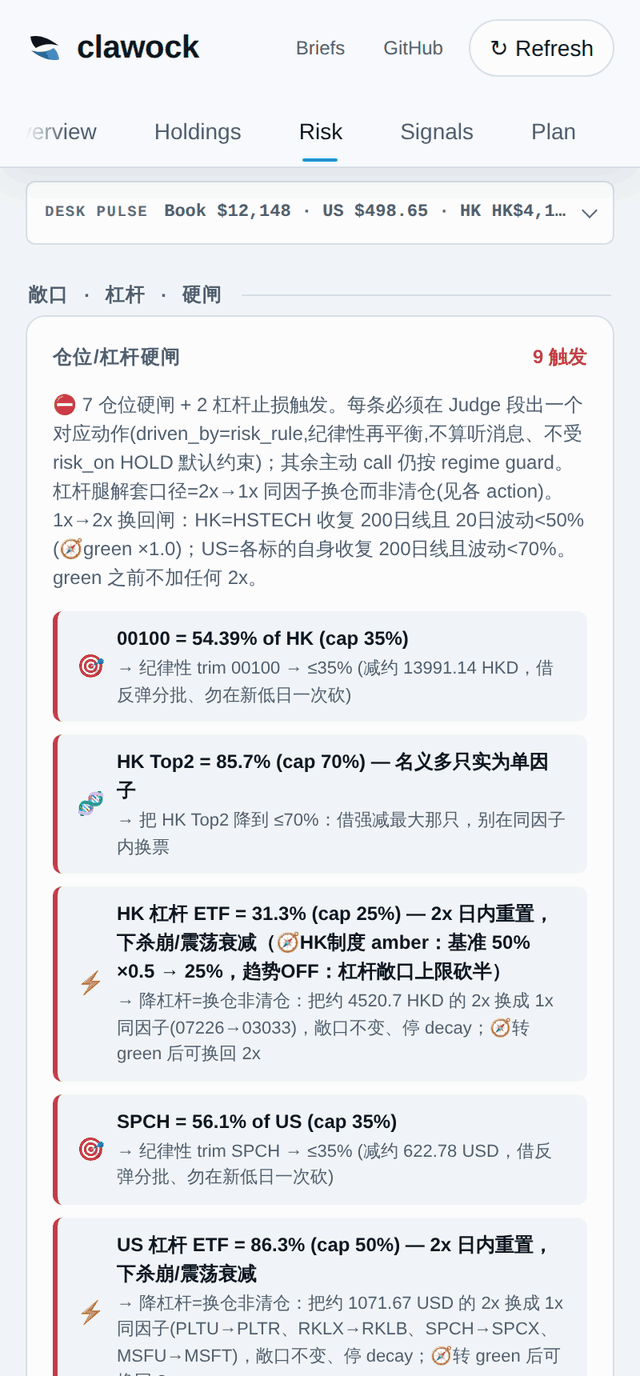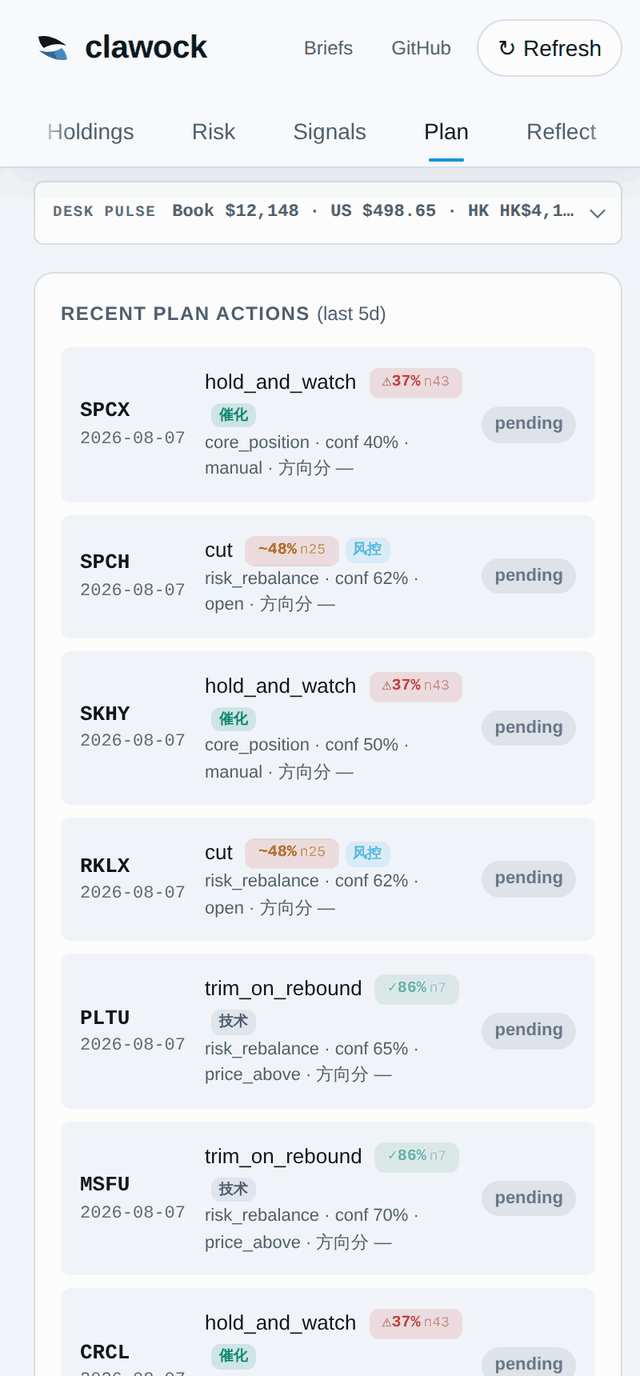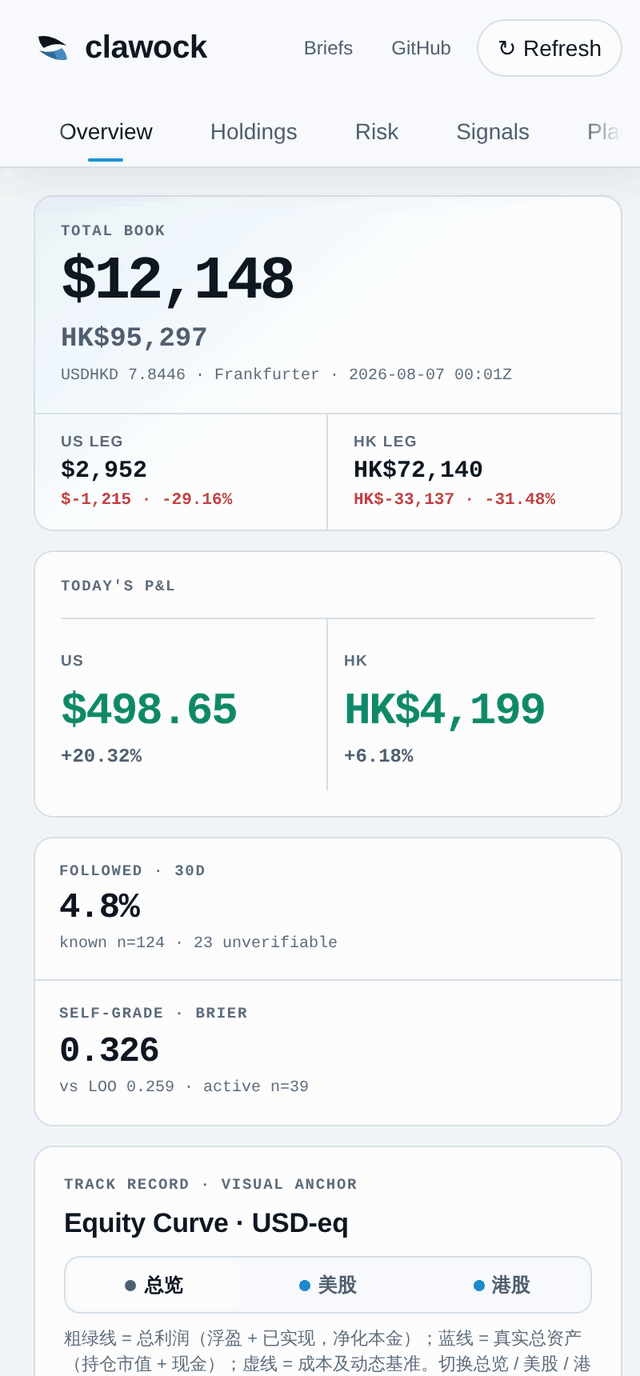
Real positions, real P&L, losses included. Numbers and charts refresh weekly; the live dashboard updates through the trading day.
What you get
You own a HK + US stock book. Each day you need to know what changed, whether to act, and how yesterday's call turned out. clawock gives the AI agent you already use a continuing investment workflow: collect information → argue both sides → settle in code → feed the result into the next decision. Claude Code, Codex, OpenClaw, DeepSeek Harness or your own CLI can carry the same contract. You still place the orders.
Here RSI means Recursive Self-Improvement: each decision leaves evidence and an outcome for the next one to build on. No promise of returns. The active calls have yet to show an edge; what you get is an accumulating record you can check.
Your daily question
What it does for you
What you get
What changed that matters to my book?
Collects quotes, filings, news and risk into context with sources
A pre-open evidence pack with timestamps, citations and named missing sources
Should I act today?
Makes bull and bear read the same evidence; states triggers and invalidation; checks money
memory/{date}-pre-open.md + memory/{date}-plan.json, then intraday trigger cards
How did that call turn out?
Settles against price bars, keeps execution status and failures, returns history and calibration
memory/decisions.jsonl, the public scorecard and reviews; portable runs also produce evaluation.json
Information in: sources before opinions
Before you open the morning brief, Python has collected quotes through fallback routes such as Tencent / Nasdaq, SEC / HKEX filings, Eastmoney capital flow, bilingual news, macro and sentiment, then reconciled your book, FX and risk. Old news is labelled separately from live information. A failed source says “not fetched,” never “no news.” Hong Kong has the base coverage, but its research breadth is behind US.
You get an evidence pack. On the live desk, preflight writes the core needed for this judgment and reference layers the agent can load on demand. The agent can trace the batch without reconstructing it from chat. In your own harness, run prepare produces request.json, pinning per-file and whole-context SHA-256 hashes, the workflow version and the whole-pack certificate.
Certification pins what was used. Citations carry the source and publication or observation time; hashes check content and generation, not whether a news story is true. Source access credentials and model API keys remain with your runtime, outside the public repository. The portable skill also lets your agent use its own research tools to add traceable evidence; scheduled desk jobs read the Python-assembled files.
The live desk’s full information and delivery flow
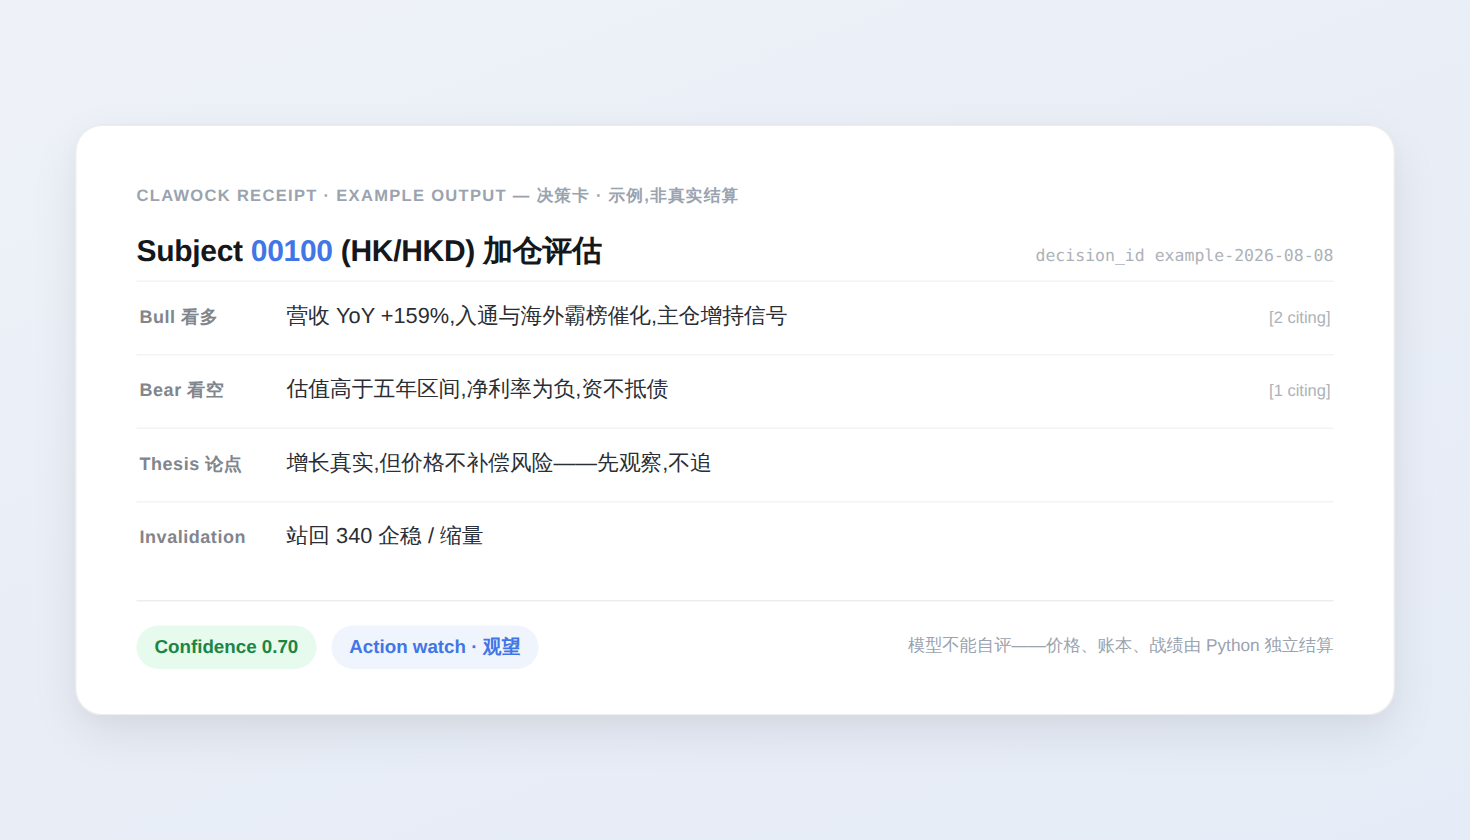
Ask “Can I add to this position today?” The agent writes the supporting case, the opposing evidence that could overturn it, then an action, trigger, confidence and thesis invalidation conditions. On the live desk, analysts, bull/bear researchers, risk voices and a judge run that debate. The portable workflow takes the same evidence and opposing-case requirements into your current agent.
You get a plan and a receipt. The desk leaves a daily brief and plan.json; intraday cards compare fresh quotes with the morning's triggers. A portable run produces decision.json. Python checks citations, opposing evidence, invalidation and order / FX arithmetic before returning a generation-pinned publication receipt. Without an opposing case it refuses publication. Conversation verdicts on the live desk enter the ledger through clawock record --source <harness>. You decide which orders to place.
Example output, not a settled call.
The live desk’s full bull / bear debate
The desk debate is adapted from TradingAgents; the judge names the strategy frame behind each call.
After the close: results feed the next decision
The close is not the end of the conversation. You use mark-followed to mark followed / not-followed execution evidence. Code checks triggers and outcomes on canonical bars using each market's calendar, groups repeated calls on the same thesis into one episode, and keeps the ungradeable cases visible.
The next decision starts from this record. The next live brief reads decision metrics, past reviews and confidence calibration. Calibration uses earlier dates only, shrinking or abstaining when evidence is thin. A failed call stays linked to its original evidence, so the agent can revisit yesterday's reasoning instead of starting the story over.
A different harness can continue the feedback. Portable runs turn source-linked outcome.json into evaluation.json (a directional evaluation, not realized P&L). An evaluation or rejection receipt can anchor a bounded proposal, applied after a named review accepts it, with a rollback record. Today those parameters govern evidence counts and the confidence cap without a primary source; they cannot silently change strategy, trading rules or the skill. This is a reviewable improvement path, not an automatic increase in returns.
Every call is settled mechanically and published: wins, losses, and the cases
that can't be graded. Nothing is hand-tuned after the fact.
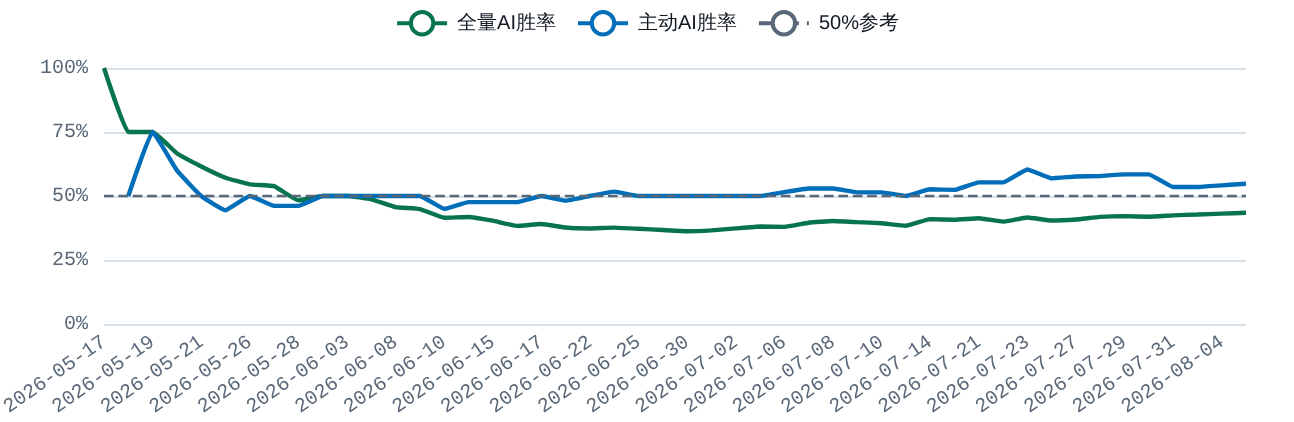
Cumulative episode win rate against a 50% directional-hit line: how often the direction was right, not what it earned. Refreshed weekly by GitHub Actions; live figures are on the Holdings tab.
Read it with these limits in mind:
A diagnostic, not proof of return. Keeping the model away from its own score stops the desk grading itself. It does not make the market data or the metric definitions correct, and a direction hit rate is not money earned.
The active calls have yet to show an edge. A factor whose bootstrap interval straddles 50% stays out of decisions, and the leverage dial's timing cannot be distinguished from chance. Both results are published in Reflect.
The shadow portfolio is simulated, not live. Its gross figure carries no commission and no spread; a net figure with a pre-registered cost haircut is published beside it, and market impact is not modelled.
The account result is human plus model. The owner decides which calls to follow, and every call carries its followed / not-followed / unknown status.
Any harness, one decision contract that accumulates evidence
Use the same investment-decision skill and artifact contract in Claude Code / Codex / OpenClaw / DeepSeek Harness / any runtime that can read and write files and call a CLI. Your agent keeps its model, conversation, memory, research tools, credentials and permissions. clawock certifies inputs, validates outputs, evaluates outcomes and records improvement; it does not launch another model.
“Smarter with use” has a record you can inspect: evidence links to decisions, decisions link to execution and outcomes, history enters the next context, earlier samples calibrate confidence, and changes to evidence requirements leave review and rollback records. To switch harnesses, keep the workspace artifacts and reconnect them to context; continuity lives in those files. A new workspace needs its own capability setup to gain the author's live data feeds, schedules and history.
pip install clawock
clawock workflow install investment-decision --workspace ./my-book
clawock init ./my-book --workflow investment-decision
cd my-book && mkdir -p .clawock/work
clawock run prepare > .clawock/work/request.json
# your agent reads the request and writes decision.json
clawock run publish --request .clawock/work/request.json --artifact decision.json=decision.json
You need Python ≥ 3.11 and an agent that can read a file and write
decision.json; the model call stays in your runtime. CI runs
this same block
on every pull request against the wheel alone. No model at hand?
bash examples/cli/minimal-run/run.sh smokes the whole lifecycle without one,
with no credentials and no broker, or open a Codespace:
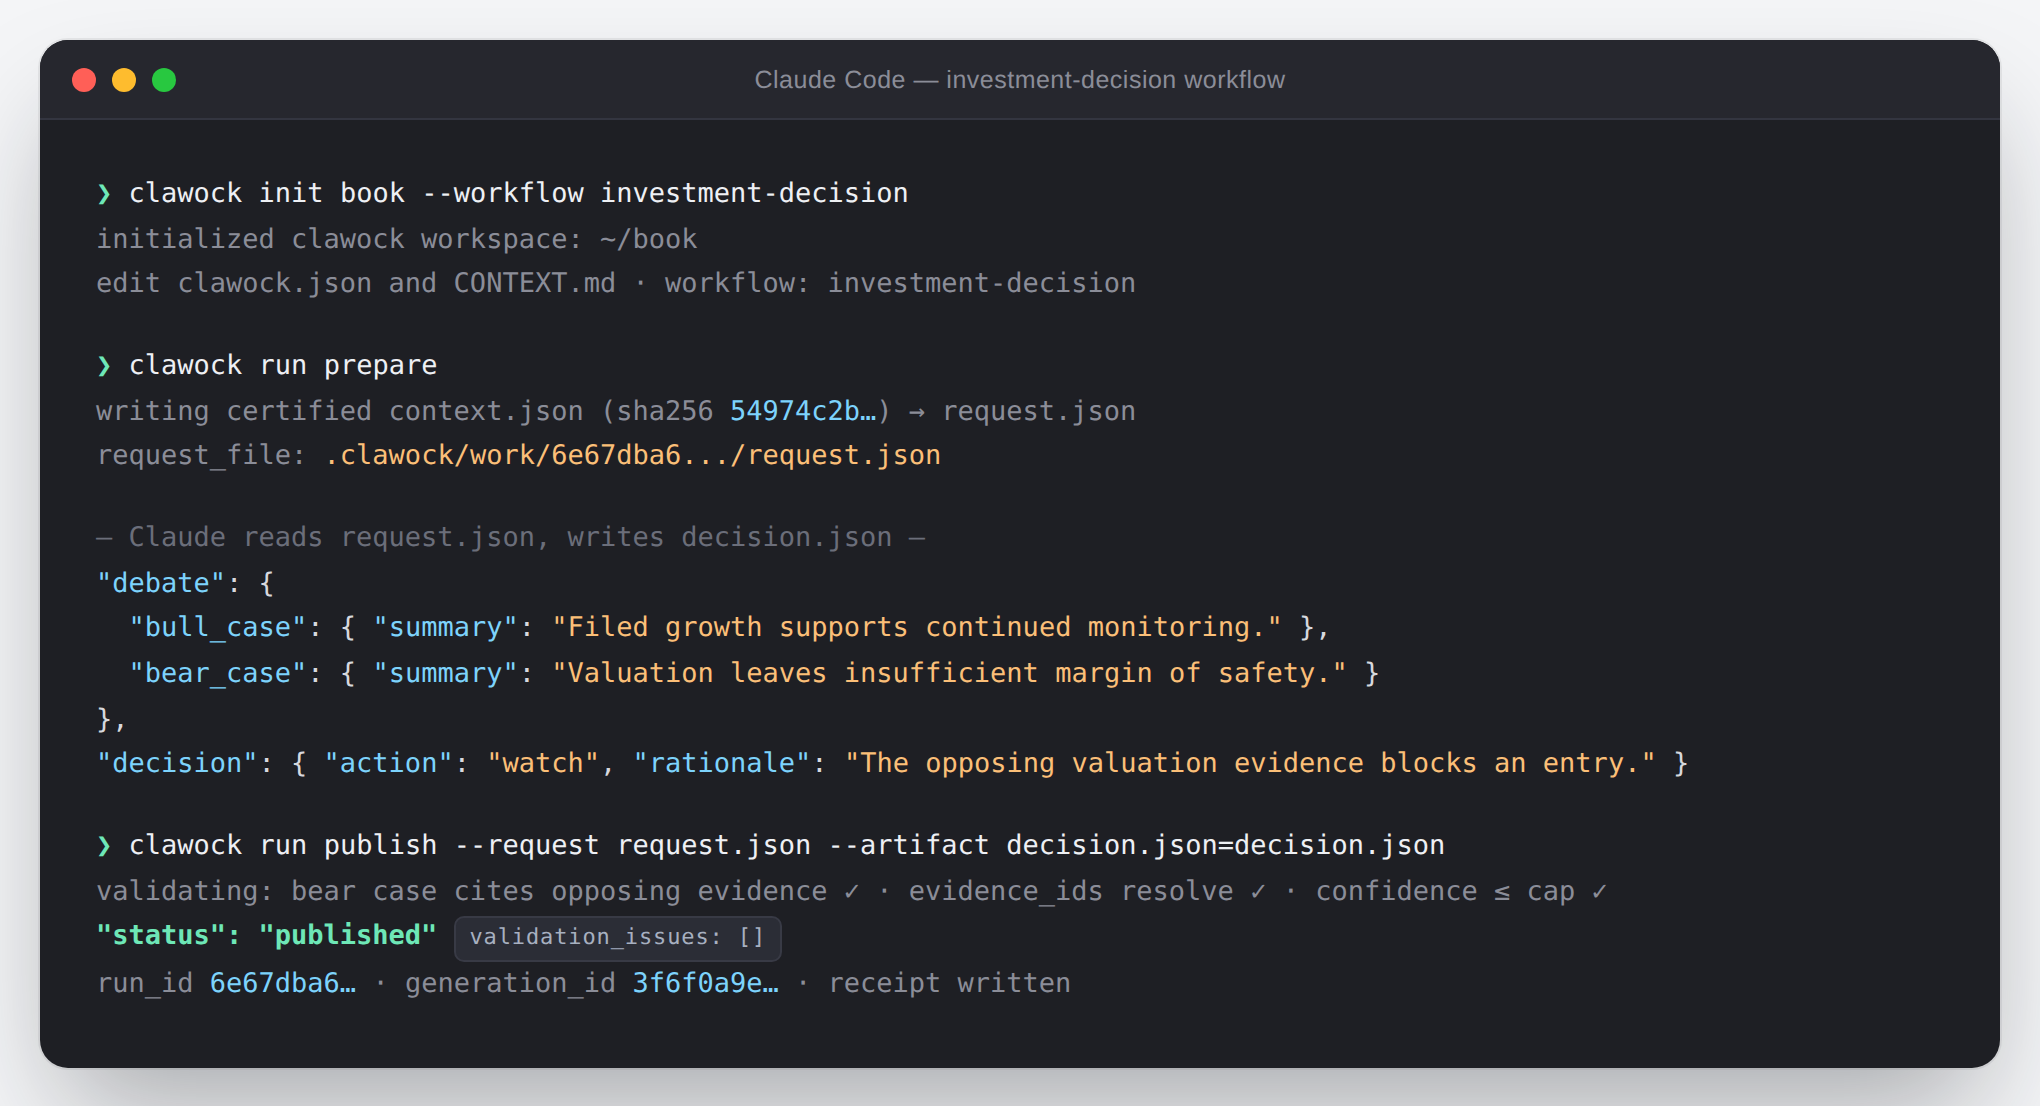
Drop the opposing evidence from decision.json and publish refuses it (exit code 1):
{
  "status": "rejected",
  "validation_issues": [
    {"code": "insufficient_opposing_evidence", "message": "requires at least 1 opposing evidence item(s)"},
    {"code": "unsupported_bear_case", "message": "bear_case must cite opposing evidence"},
    ...
  ]
}
Here is the whole run inside Claude Code, from the
examples/claude-code instruction:
Harness views and background work
The DeepSeek Harness desk views and background queue
Delegate a task, leave the chat, come back to a result.clawock-dsh brings
an investment-decision skill, a Decision Mind tab and a provider panel into the
dsh web GUI. On a host with clawock's agent-dispatch runner, that panel also
puts your Claude Code, Codex and OpenCode background team within reach: you ask
in chat for a repository change with its delivery contract, the runner keeps the
task alive, and the plugin lets you see and steer it.
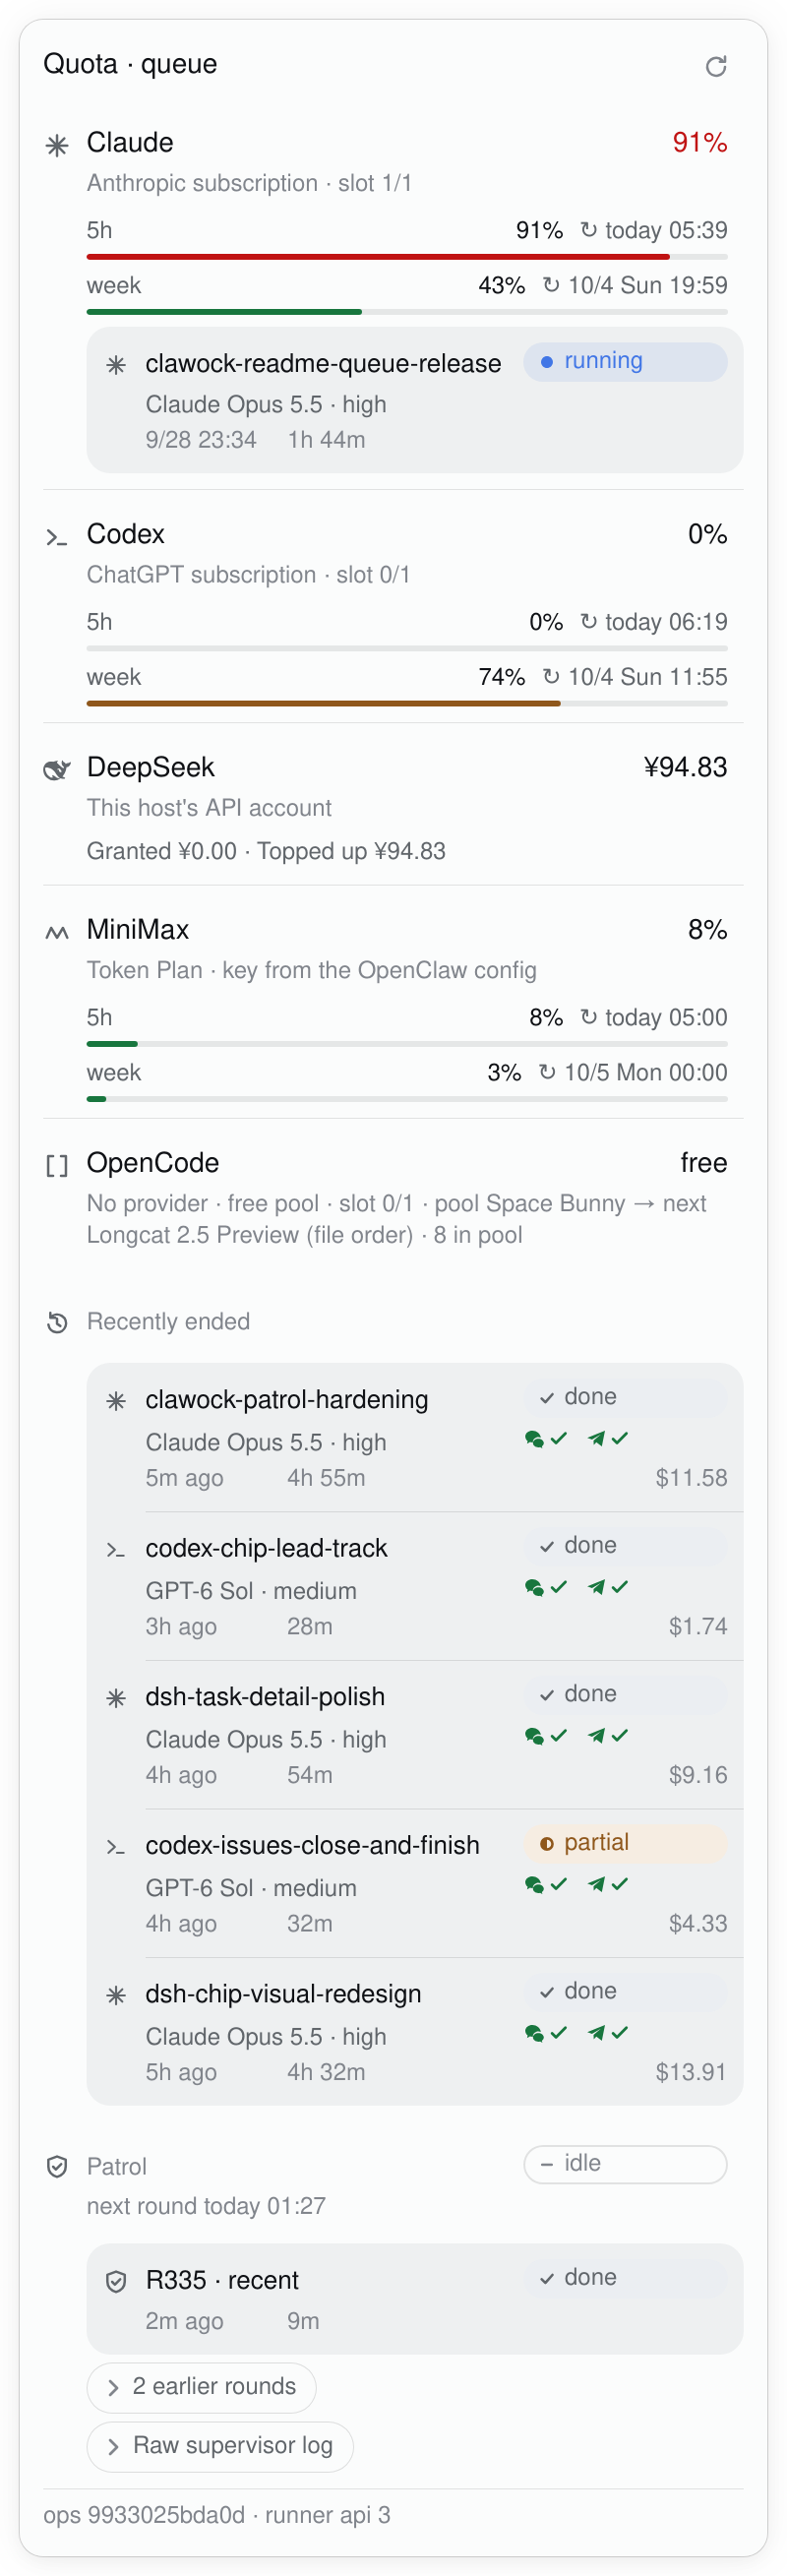
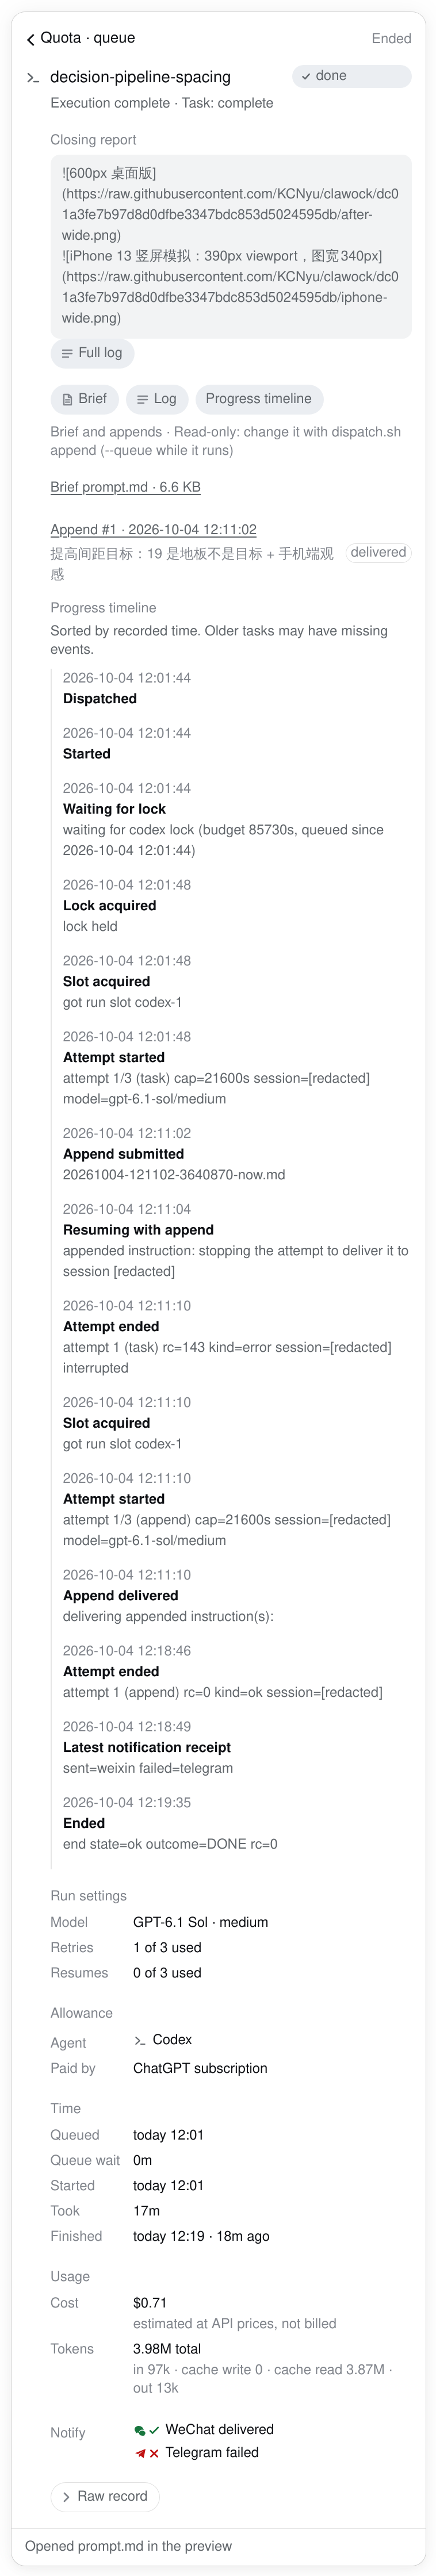
See what is happening. Subscription use and reset times, provider balances, each agent's real queue, model, elapsed time and API-price cost estimate share one panel.
Change course while it runs. Move waiting work up, change the next attempt's model where allowed, adjust deadlines and retry budgets, cancel a task or retry an unfinished session.
Keep the result in reach. A completed task with a failed send stays visible; a missing message does not erase the work.
The full-size queue capture — the real plugin on a live host
A task's history — append instructions and the progress timeline
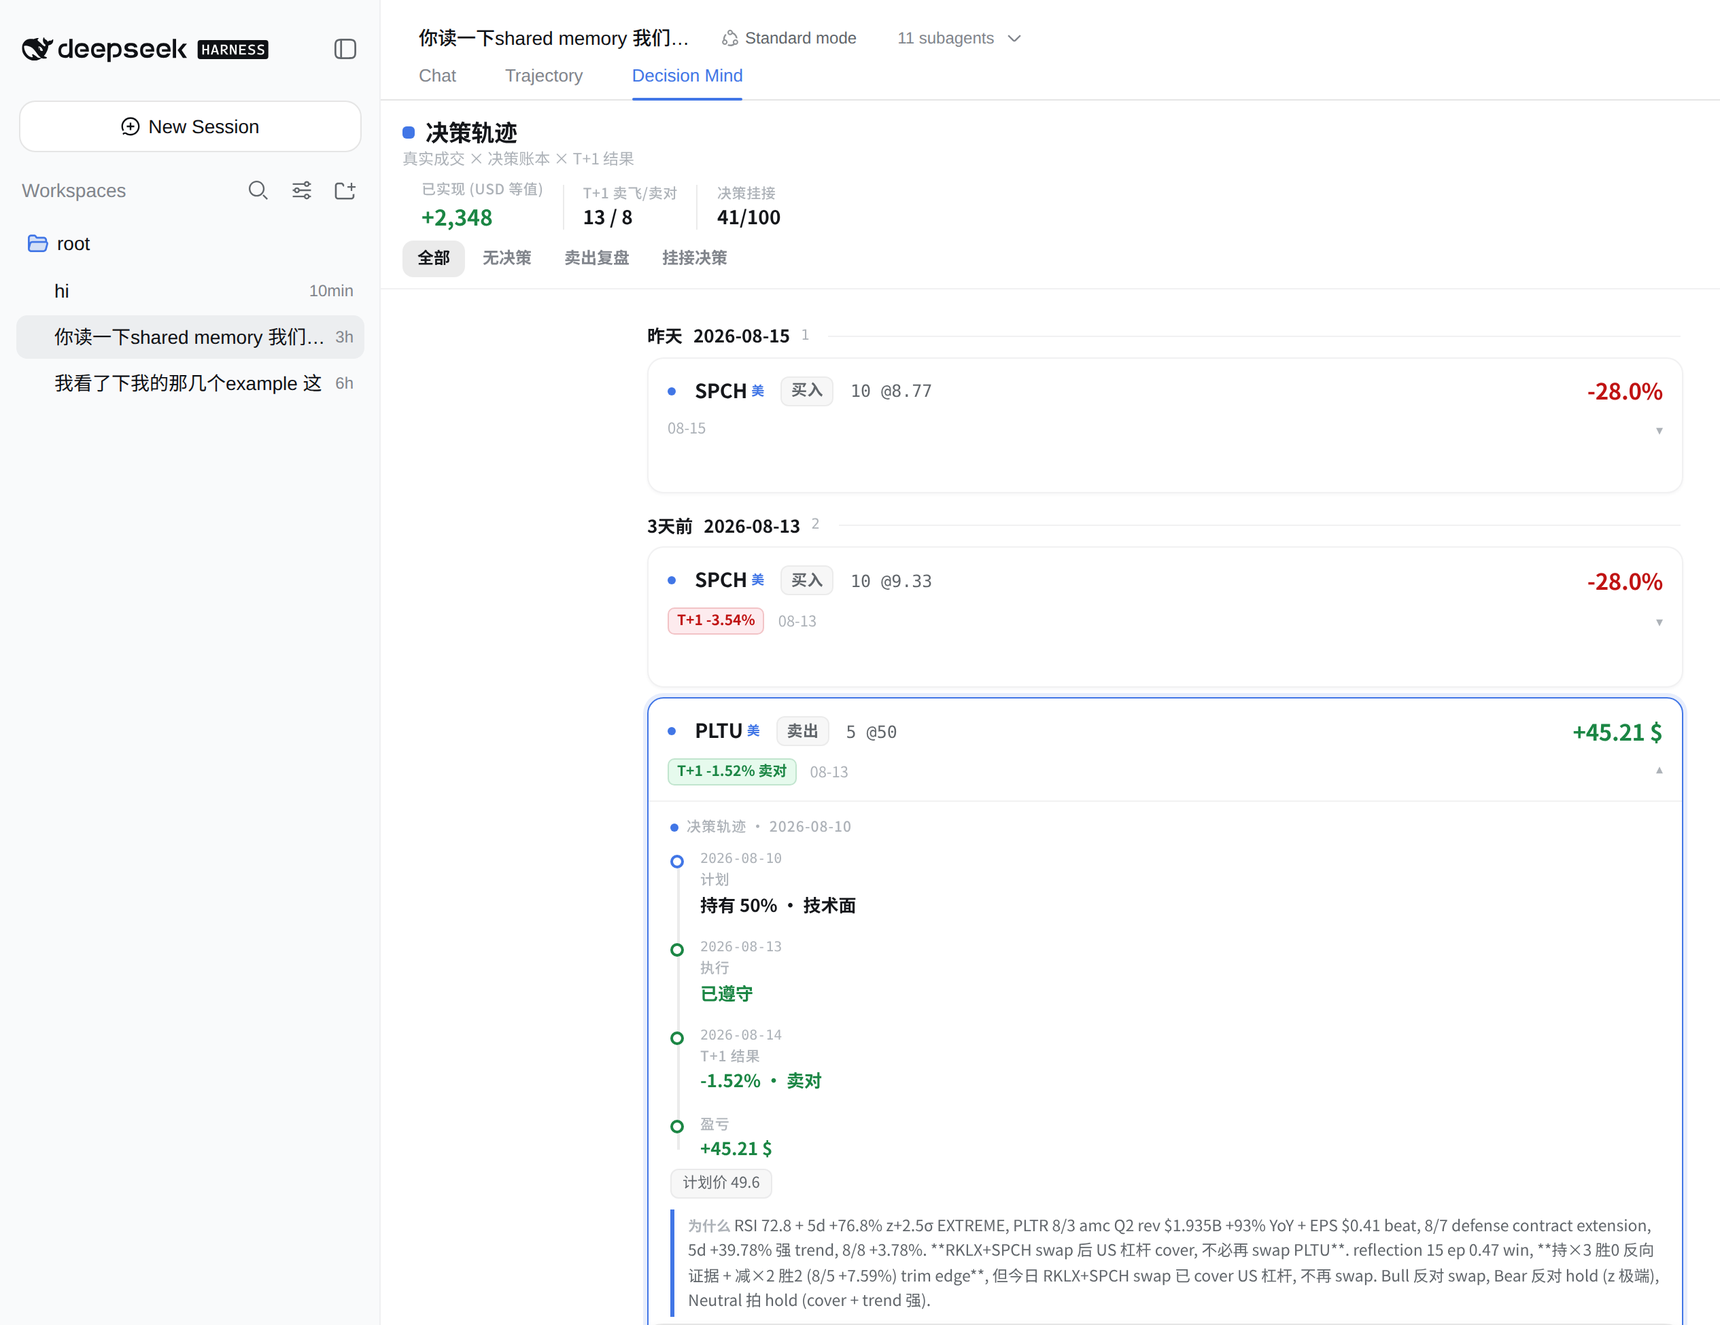
Ask “Can I add to 0700.HK?” and the investment skill takes the agent through
evidence, a bull/bear debate and a bounded decision. Decision Mind then lets
you open a real fill and follow plan → execution → T+1 → P&L. Missing plans
and ungraded fills say so, USD and HKD stay separate, and you place the orders.
Restart the web profile to load it. Queue controls also need the host runner;
without it the panel still shows provider allowances and balances.
npm package ·
installation and queue setup.
Under the hood
How the same loop runs on the author’s real stock book:
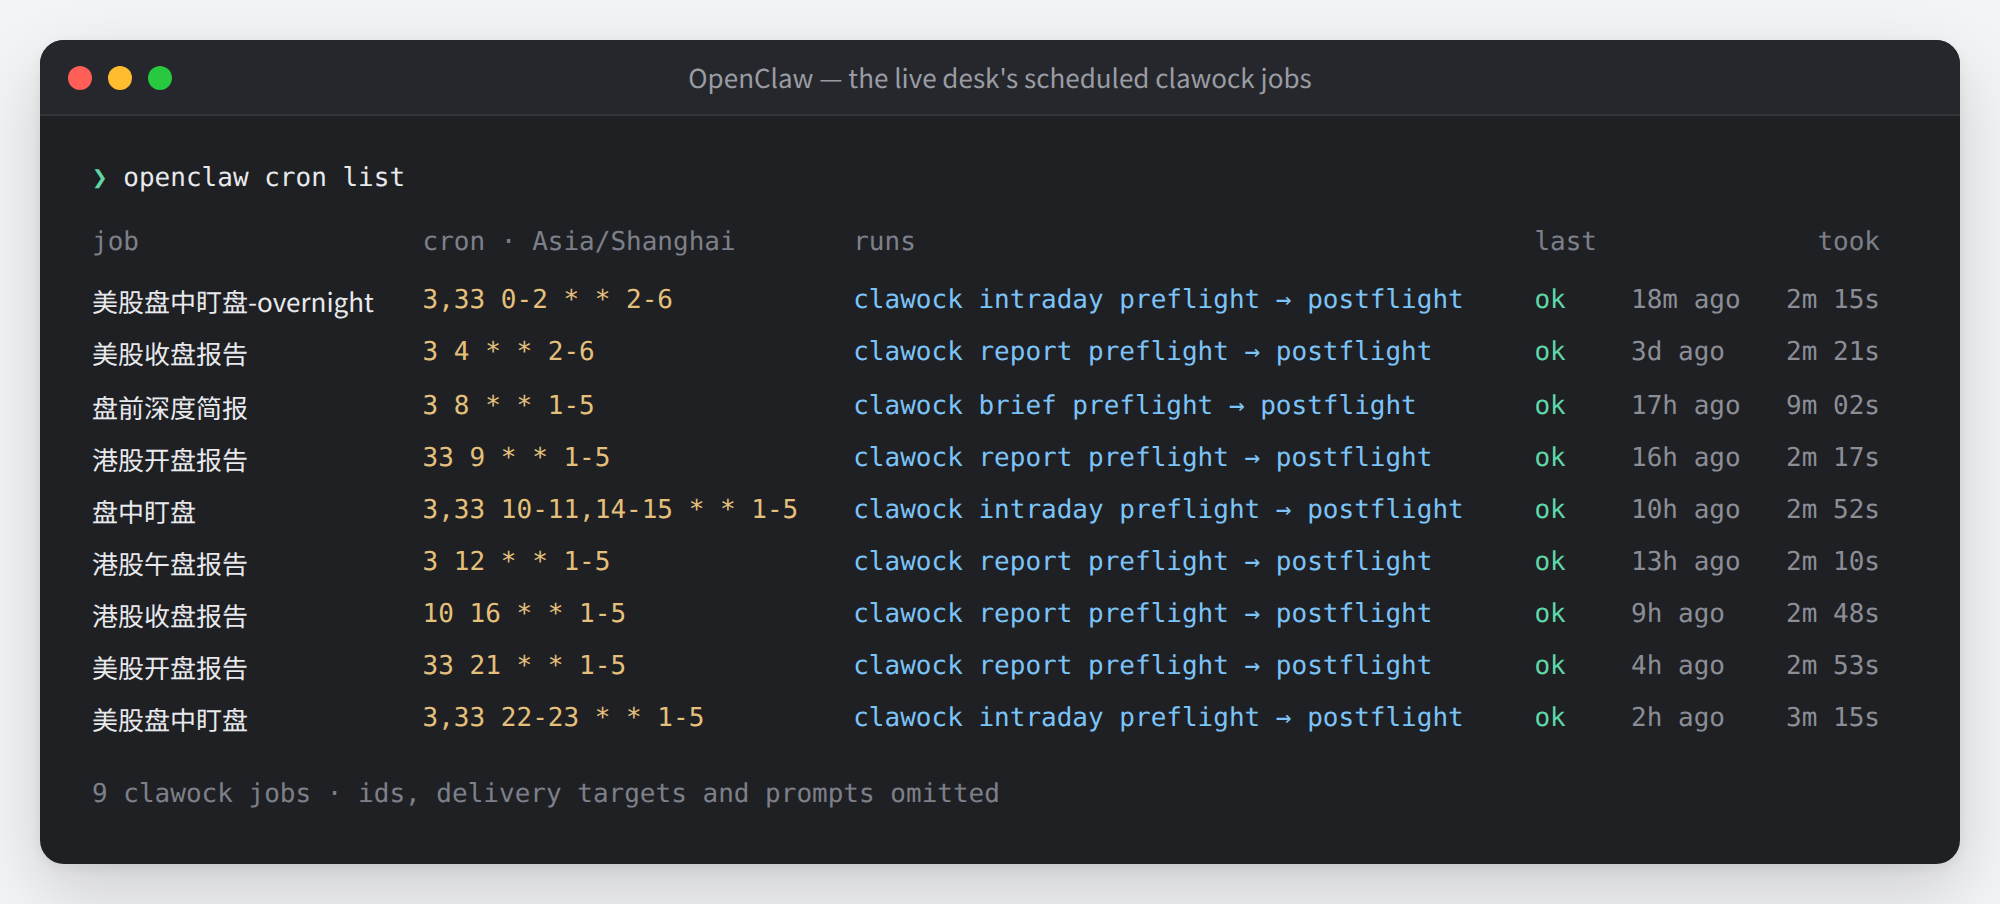
The author's desk sends the pre-open plan at 08:03 HKT and runs this unattended on OpenClaw. Each job is
clawock … preflight, then the model writes, then clawock … postflight:
Rendered from the host's real openclaw cron list --json by site/tools/shoot_openclaw_cron.js; job ids, delivery targets and prompts are left out. The full timetable is the generated schedule.
How the desk works covers the information layers, run context, settlement rules and code gates.
Explore
Live dashboard — positions, risk, and the code-graded scorecard.
They expect clawock's scripts, data contracts and memory files; they are not standalone one-command products.
Built with Claude Code, the openclaw cron daemon, a static Jekyll + GitHub Pages frontend, and Python. Market, news, macro, and sentiment come from documented public sources; see third-party data and service terms before reusing any fetched content.
Scope, disclaimer, and license
This repository holds real trading positions. It is a personal record and portable workspace — not investment advice, a recommendation, or a copy-trading system. The desk analyzes and proposes; it does not place orders for you. No individual outcome is hand-picked — settlement rules and methodology changes are versioned in code — the active calls have yet to show an edge, and every number may be stale by the time you read it.
Original code is under the MIT License. Adapted third-party code keeps its own license and attribution in NOTICE and THIRD_PARTY_LICENSES/. Third-party market data, news, social posts, filings, trademarks, and API access are not relicensed by MIT — see Third-party data and services.
本地私有、开源的自进化跨平台 AI 内容发现 Agent:先理解你,再主动从 B站、小红书、抖音、YouTube、X、知乎、Reddit、微博等平台与开放 Web 寻找内容。(支持 deepseek harness 插件) | Local-first open-source cross-platform AI content discovery agent: understands you, then proactively finds content across Bilibili, Xiaohongshu, Douyin, YouTube, X, Zhihu, Reddit, Weibo and the open web.(support deepseek harness plugin)